
What is gputaskman?
gputaskman is a terminal GPU task manager that connects per-process GPU memory and engine activity with the runtimes, model files and LLM buffers each process has loaded. The README describes it as an htop for what is inside a GPU rather than only how full it is: where Windows Task Manager reports a used total, gputaskman tries to split that total into model weights, KV cache, browser surfaces, the desktop compositor and memory held in system RAM. The project is written in Python with the Textual TUI framework, psutil and NVIDIA's nvidia-ml-py binding, and the package metadata lists Scott Hanselman as author. The repository opened on November 3, 2026, and the project labels itself early, experimental software.
Platform coverage differs by vendor. On Windows it reads WDDM per-process counters for NVIDIA, AMD, Intel and Qualcomm adapters, with device telemetry from NVML on NVIDIA and from the AMD Display Library on supported AMD drivers, while Intel and Qualcomm device GPU activity comes from WDDM counters. On native Linux it supports NVIDIA through NVML, AMD on the amdgpu driver, Intel on i915 and Huawei Ascend 310P accelerators through npu-smi. Under WSL the current release covers only NVIDIA, with Linux process sizes matched from the Windows host counters. macOS support is limited to Apple Silicon and reads IOAccelerator statistics, Metal client GPU time and the footprint tool. Cloud services, CPU-only and NPU-only workloads are outside its scope, and the tool does not dump VRAM or list a game's textures.
Distribution follows several routes listed in the README: the gputaskman package on PyPI for uv tool install or pipx with Python 3.11 or newer, portable ZIPs for Windows x64 and Windows ARM64, portable tarballs for Linux x64 and ARM64 that need glibc 2.35 or newer, a Nix flake for x86_64-linux and aarch64-linux, and a clone run with uv run --locked gputaskman. macOS has no portable download yet. The Windows builds are unsigned, ship with a .sha256 companion file and need no Python, CUDA Toolkit or administrator session.
The latest release is v0.4.1, published on November 13, 2026. It lists NVIDIA GPUs in TCC mode on Windows with VRAM read from NVML, a path the README marks as covered by mocks and not validated on TCC hardware. The release reports device GPU activity for Intel adapters from WDDM engine counters, treats Intel and Qualcomm adapters with at most 512 MiB of dedicated memory as integrated GPUs whose per-process usage counts as shared system RAM rather than VRAM, and renames the process table column for GPU-accessible system RAM to Shared. It also identifies models loaded by the Foundry Local daemon on Snapdragon, adds a path-arg evidence label for model files passed under custom launch flags, reads the Windows driver version from the adapter's PnP registry entry when no telemetry provider supplies one, and makes gputaskman record report I/O failures without a traceback. Earlier releases added the Huawei Ascend 310P backend and root-only Intel load, video and power readings on Linux (v0.4.0), Intel GPU support on Linux, the system RAM and CPU panel and the record command (v0.3.5), and gputaskman diff, macOS, AMD on native Linux and the Nix flake (v0.3.1). AMD GPU support under WSL through ROCm's AMD SMI bindings, and llama-server and vLLM /metrics gauges for running requests, waiting requests and KV-cache pool usage, are on the main branch, not yet in a release.
The code is released under the MIT License. The README separates measured counters from estimates: device and process counters are measurements, while process classifications and GGUF-derived weight and KV-cache figures are estimates, and each live hardware check is documented with its GPU, driver and workload. Features covered only by mocks or unit tests, such as TCC-mode GPUs and multi-GPU Windows setups, are listed as not yet validated on hardware, and per-process data for Intel xe cards is not decoded yet. A full guide to installing and using gputaskman is on the iThub blog. Other process and hardware monitors on iThub include Argus for Windows and Mole for macOS.
gputaskman screenshots
Explore the interface. Open a screenshot to view it at full size.
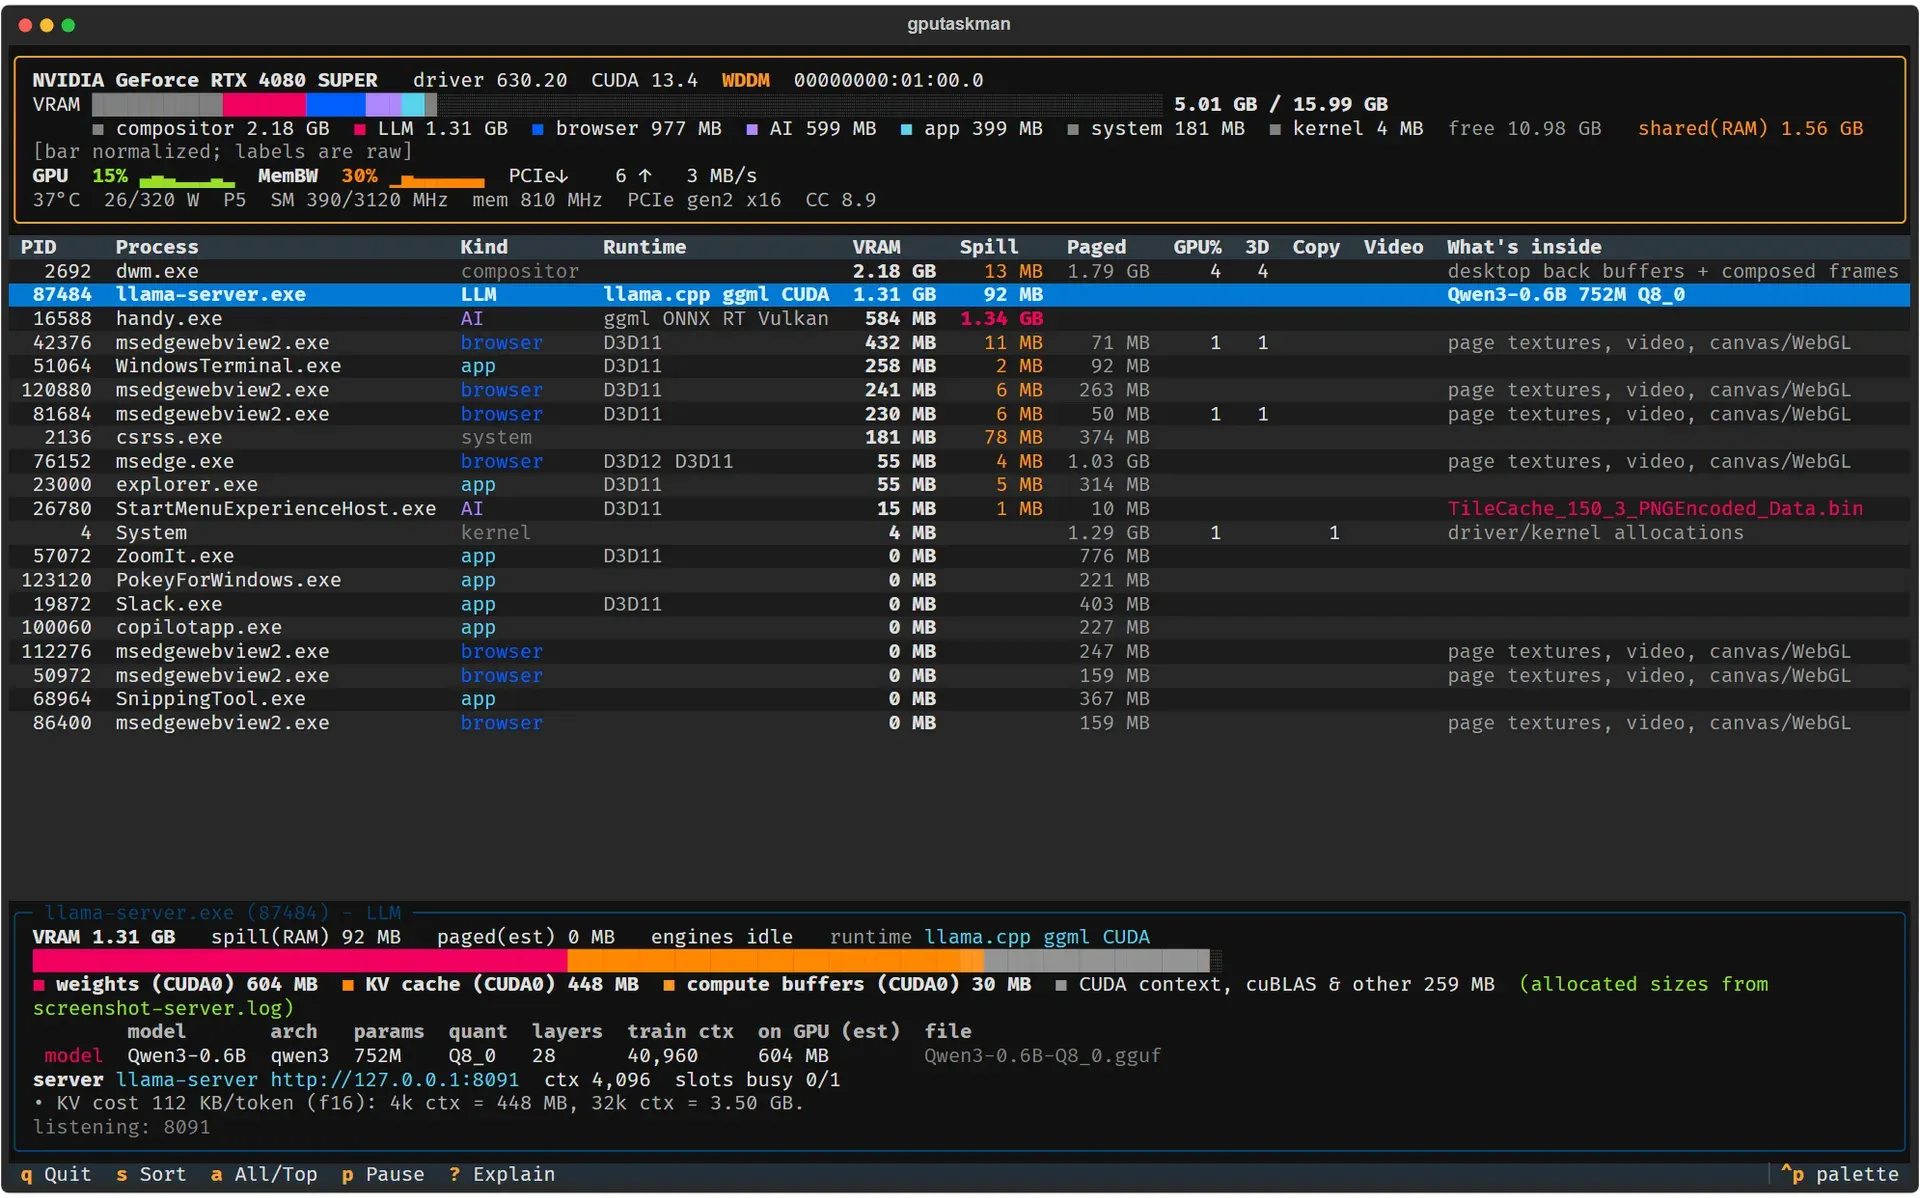
Live overview: VRAM split by category, the process table and the inspector for a llama-server process running Qwen3-0.6B.
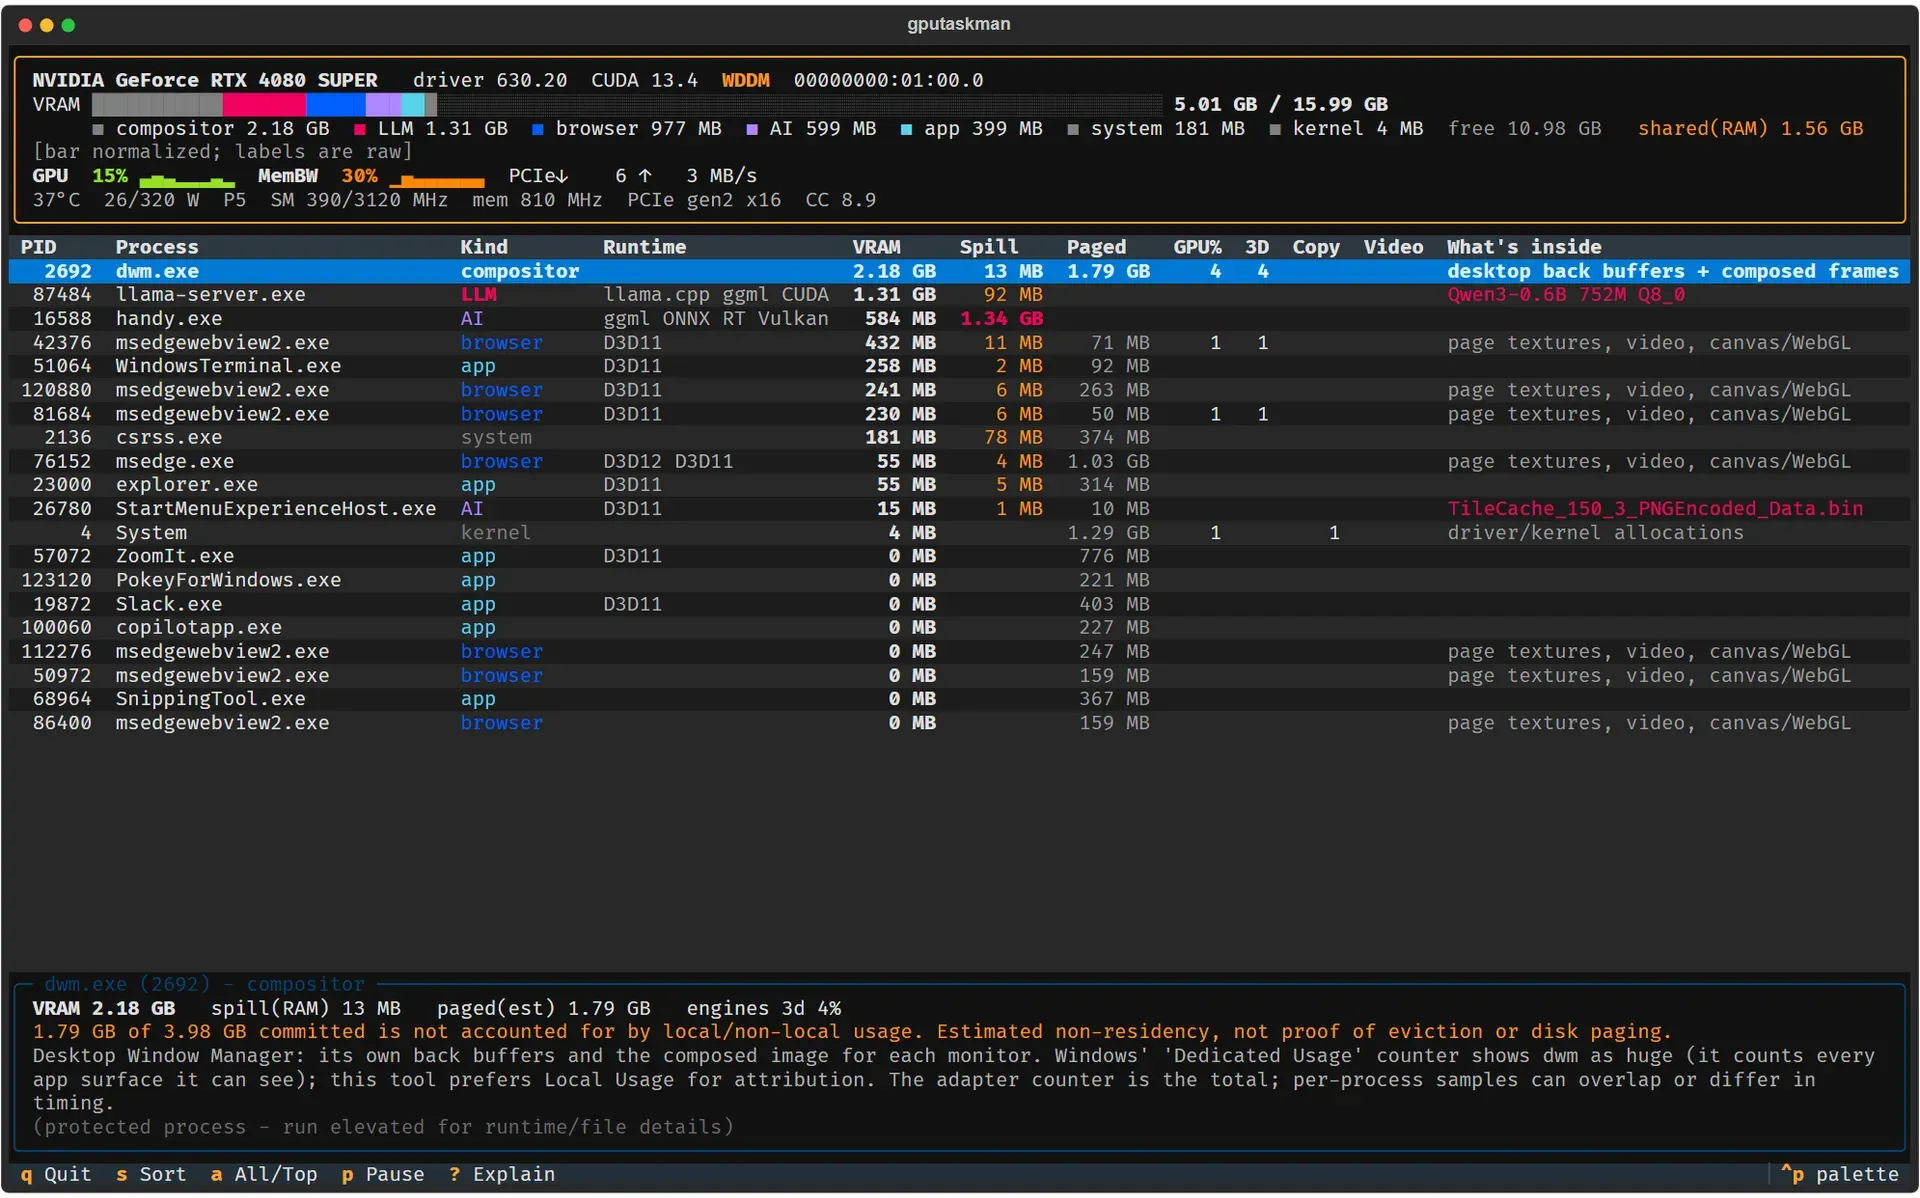
Compositor row selected, with the inspector explaining Dedicated Usage versus Local Usage accounting.
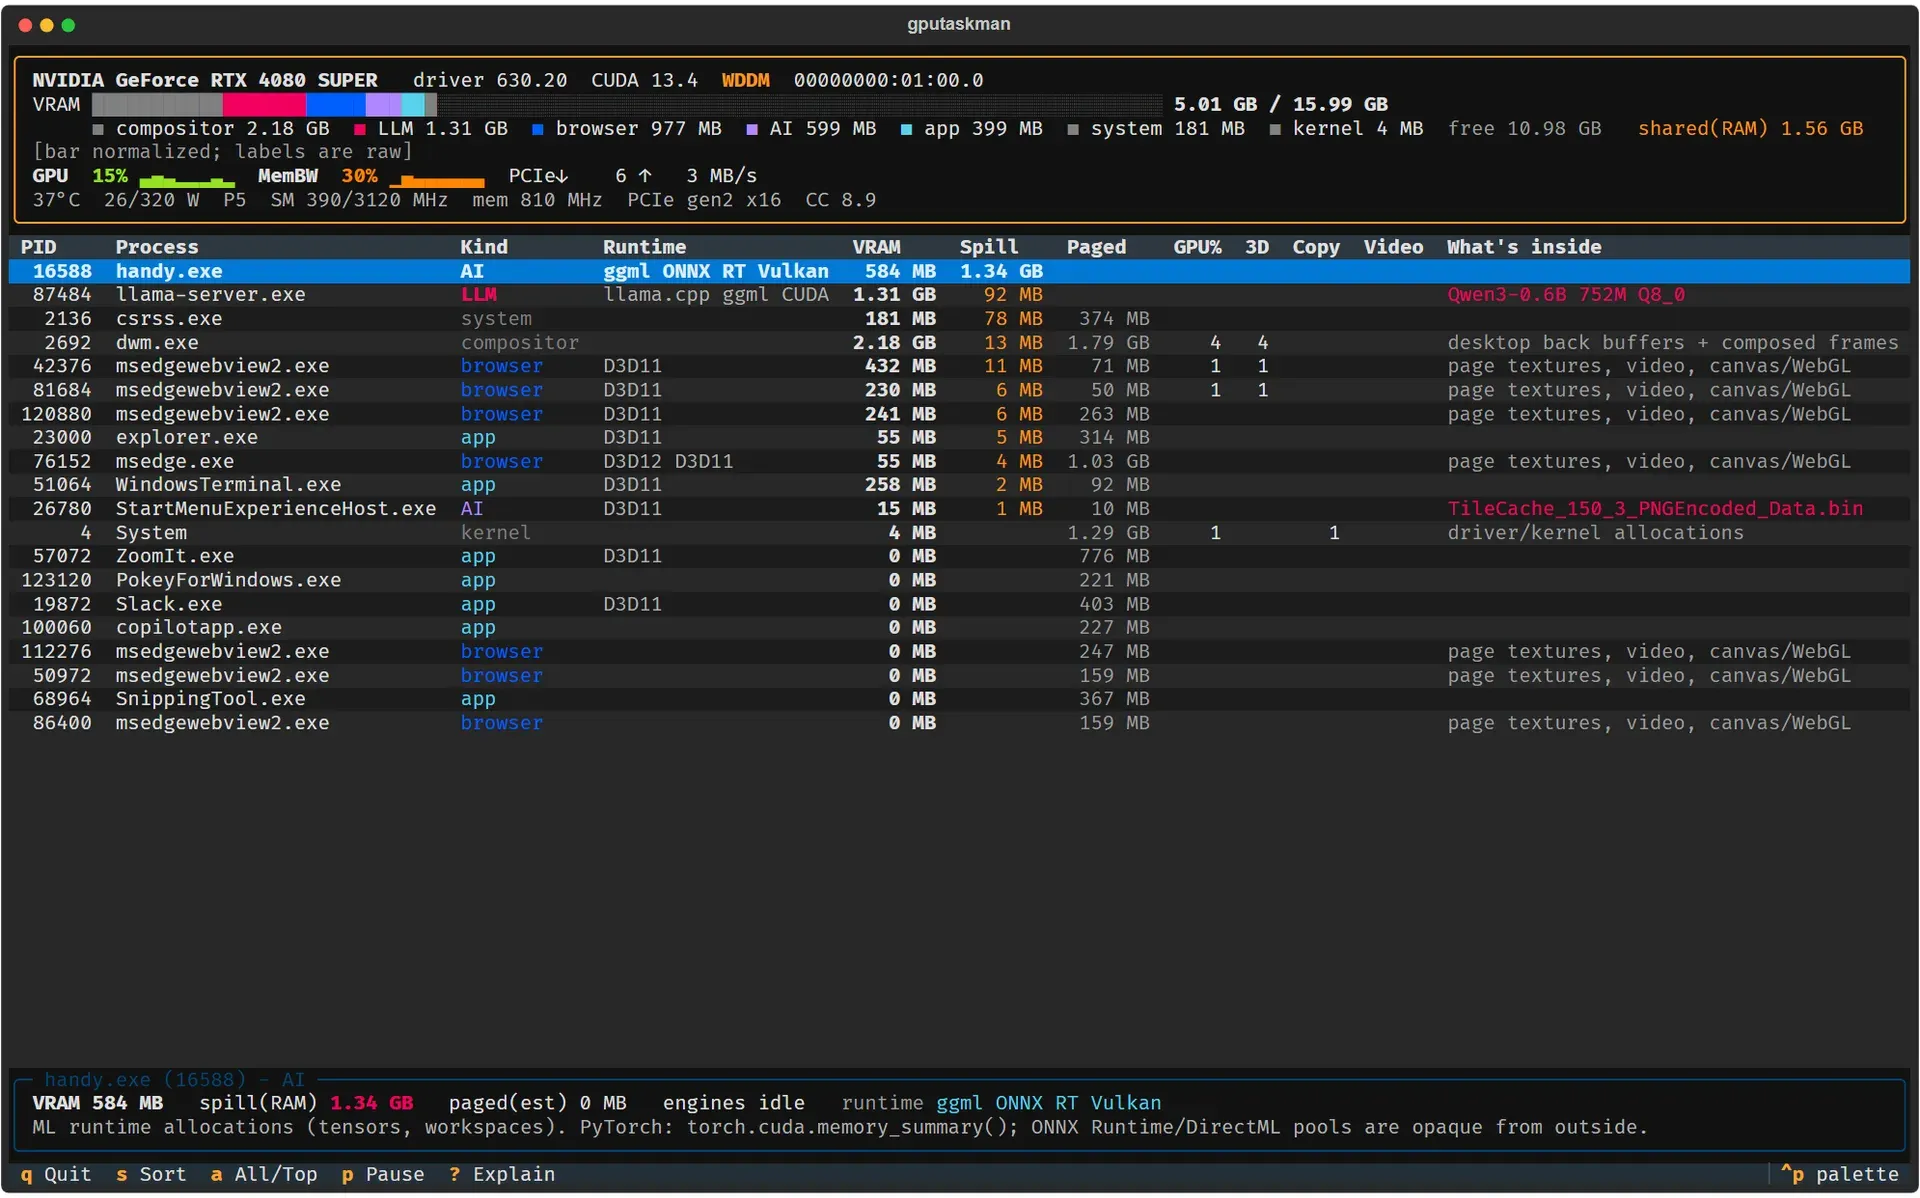
Processes sorted by GPU-accessible system RAM, with the selected AI process and its runtimes in the inspector.
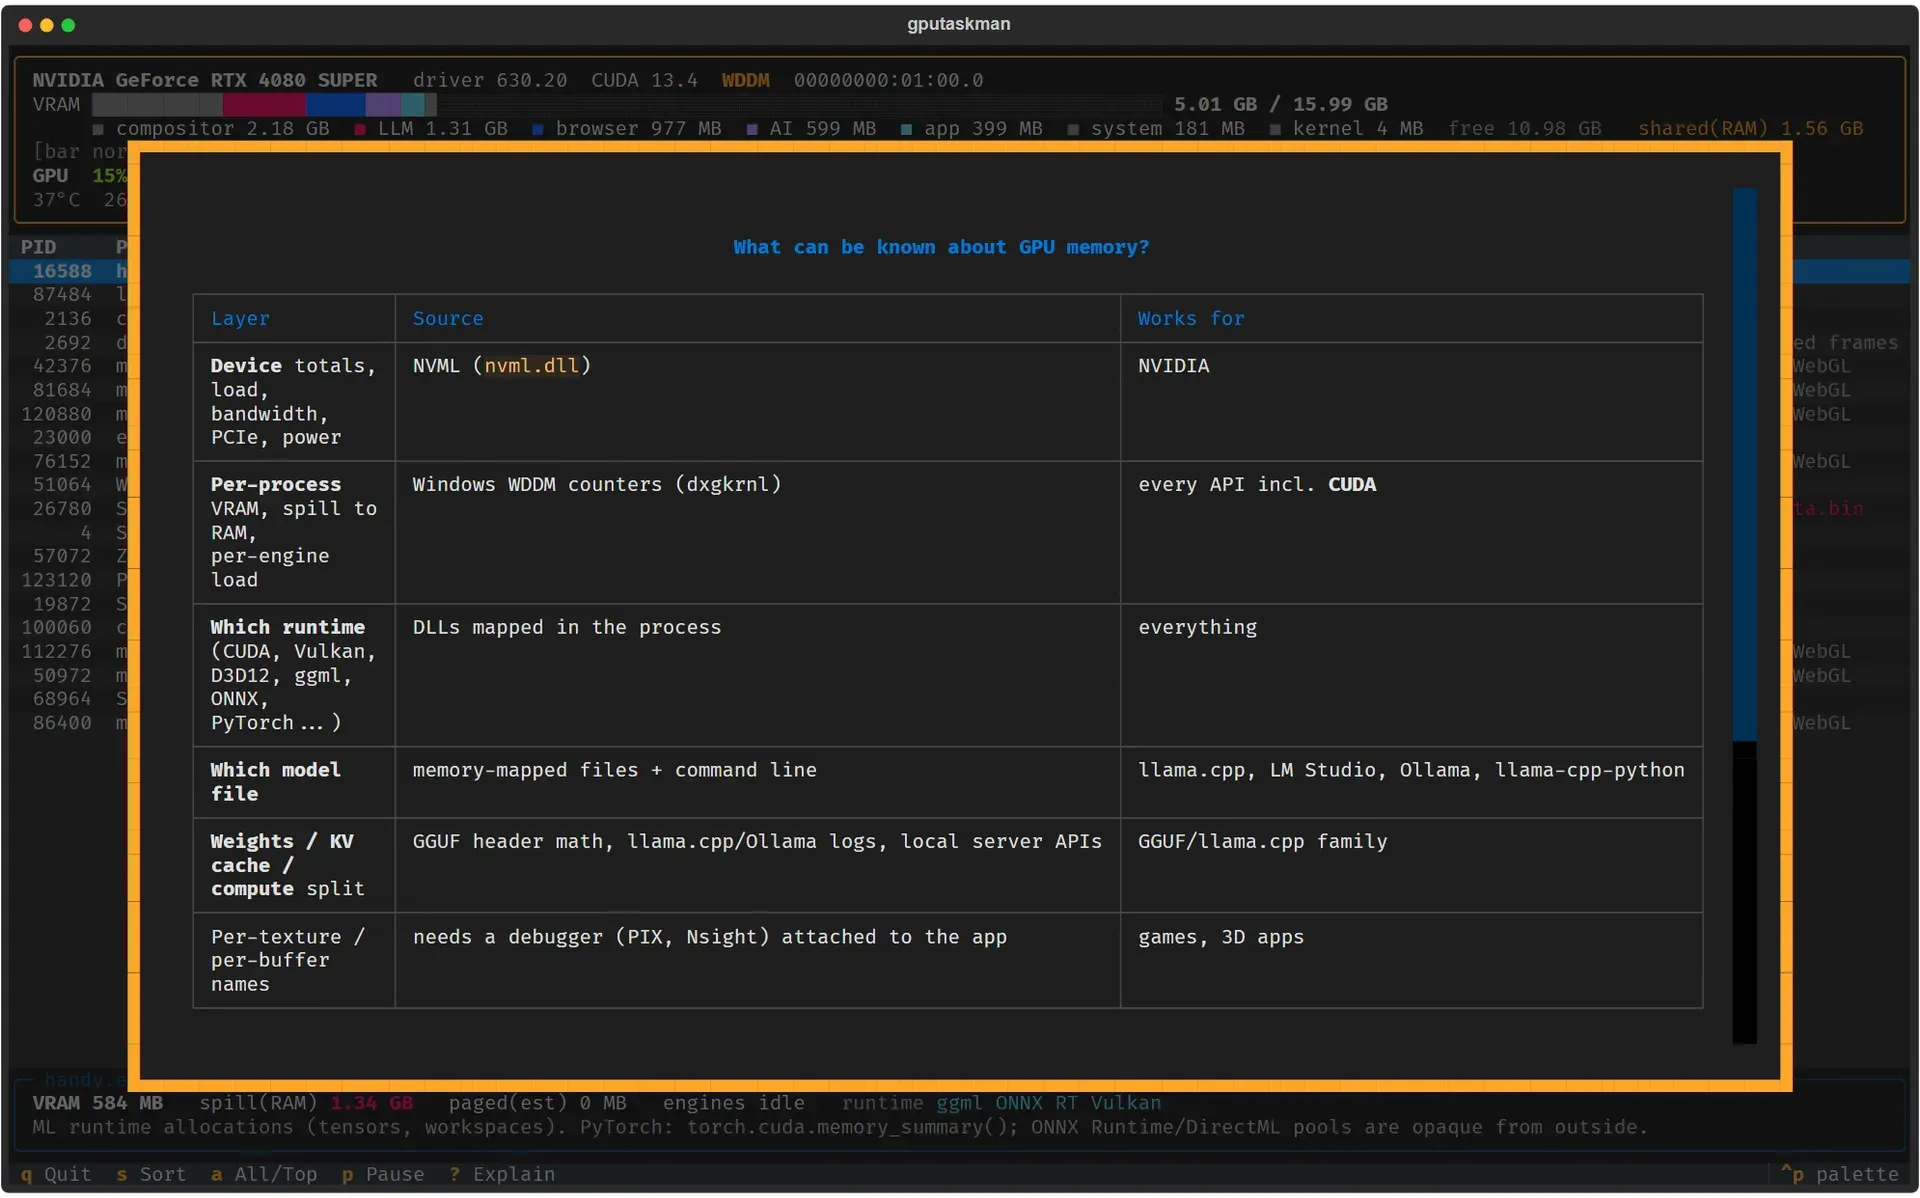
Built-in help dialog listing what can be known about GPU memory and from which source.
Source: official gputaskman project page.
Key capabilities
- Device view Each GPU header shows VRAM used and free, a VRAM bar split by process category, GPU activity, memory activity, PCIe traffic, temperature, power, clocks and driver details. Eight history charts cover GPU, SM or GFX clock, VRAM, memory activity, temperature, power, encoder and decoder, and the Charts dropdown or the
ckey focuses a single metric. Readings a driver does not expose appear asN/Ain the TUI andnullin JSON rather than as zero. - Per-process GPU table The process list shows PID, process name, kind (compositor, LLM, AI, browser, app, system, kernel), detected runtime, VRAM, Shared, Paged, GPU% and per-engine load for 3D, Copy and Video, plus a What's inside column. The
skey cycles the sort through VRAM, GPU%, shared system memory, paged, name, RAM and CPU%. On Windows the values come from WDDM counters, which attribute memory across Direct3D, Vulkan, OpenGL and CUDA. - Runtime detection Mapped DLLs and shared libraries identify runtimes such as CUDA, HIP, Vulkan, Direct3D, ggml, ONNX Runtime and PyTorch. The README states that a loaded DLL is detection evidence only and does not prove that the library is doing GPU work.
- Model inspector Selecting a process opens an inspector with the model it holds (LLM, decision, embedding, speech or diffusion), how it was identified, architecture, quantization, layer count, weights, an estimated KV-cache cost and buffer sizes from compatible load logs. Model rows carry an evidence label:
api,mapped,cmdline,path-argorinstalled. Two ofapi,mappedandcmdline, includingapiormapped, mark a model as confirmed;path-argis not proven loaded and does not count. - LLM runtime support Llama.cpp and llama-server get GGUF discovery, CLI settings, buffer logs and
/propsplus/v1/modelsstate, and Ollama runners are named from Ollama manifests and its/api/psendpoint; both are marked as exercised live. LM Studio, vLLM, stable-diffusion.cpp, Hugging Face cache paths and the Handy speech app have narrower support that the README lists per runtime, with LM Studio and vLLM tested on fixtures only. Since v0.4.1 Foundry Local model IDs come from the daemon's/models/loadedendpoint, labelled API-reported and live-checked with Foundry Local 0.14 on a Snapdragon X2 Elite. - Local server probing The collector sends GET requests to existing local listening ports for
/props,/slots,/metrics,/v1/models,/api/psand the LM Studio model endpoints to read context size, busy slots and throughput, and/models/loadedon the Foundry Local daemon for loaded model IDs. It never launchesollama,lmsor an inference request. When llama-server was started with--api-key, that key is sent only to the same server's port and is never stored, printed or written to JSON. - Shared and Paged columns The Shared column shows GPU-accessible system RAM, which can include pinned host buffers or allocations placed there on purpose, so the README states that it is not proof of overflow from VRAM. Paged is an estimate computed as committed memory minus local and non-local usage, not an eviction trace or a pagefile measurement. With NVIDIA on native Linux, NVML has no equivalent of the WDDM shared-memory or commit counters, so both columns stay blank instead of showing zero. AMD GPUs on
amdgpuand Intel GPUs oni915under native Linux fill the Shared column from DRM fdinfo (GTT on AMD, system memory on a discrete Intel card), while Paged stays blank because there is no commit counter; on an integrated Intel GPU system memory is shown as the process's VRAM and Shared staysN/A. - System RAM and CPU panel A System panel and RAM and CPU% columns show what each process costs the machine as the operating system reports it, through psutil, or
NtQuerySystemInformationfor the Windows process list. These figures are never added to GPU totals.--no-systemremoves the panel, columns and sampling. - Text and JSON snapshots
--onceprints a single text snapshot and--jsonprints one JSON snapshot from the same collector as the TUI. Unavailable counters arenull, and fields such ascounter_status,vram_inferred_byandstarted_atdescribe where a value came from. Output can include paths, command-line flags, model names and local ports, and the README asks users to review it before sharing. - Snapshot diff
gputaskman diff before.json after.jsoncompares two JSON snapshots and shows which memory bucket changed. Measured counters are compared separately from runtime-reported buffer sizes and GGUF estimates, processes are paired by PID, name and listening ports, and reused PIDs are detected from start times. Snapshots from different adapters that share a GPU name are refused. - Session recording
gputaskman record -o session.jsonlappends one complete JSON snapshot per interval, with--intervaland--durationoptions. Each line is flushed as it is written, so stopping the process keeps all samples so far, and since v0.4.1 a write failure such as a full drive is reported on stderr with exit status 1. The README gives about 27 KB per 52-process snapshot, roughly 100 MB per hour at one-second intervals, and the first version records one GPU. - Multi-GPU and adapter recovery On multi-GPU systems each GPU gets its own header and charts, and the process list adds a GPU column.
--list-gpuslists adapters and--gpu Nselects one; NVIDIA TCC-mode GPUs that Windows does not list are appended after DXGI adapters, with VRAM and per-process VRAM from NVML; this v0.4.1 addition is covered by mocks and not yet validated on TCC hardware. On Windows the TUI rechecks adapter topology every five seconds and reconnects adapters that are disabled and re-enabled; systems with two discrete GPUs and multi-GPU Windows are listed as not yet validated. - Windows support The Windows backend needs 64-bit Windows 10 or 11 with a current WDDM driver and runs on x64 and ARM64. NVIDIA device telemetry comes from NVML, which ships with the driver, and AMD telemetry from the AMD Display Library or an optional AMD SMI Python installation. Intel and Qualcomm adapters use WDDM per-process memory and engine counters and WDDM device GPU activity; temperature, power, clocks and memory activity are not available for them on Windows. An Intel or Qualcomm adapter reporting at most 512 MiB of dedicated memory and more shared memory is treated as integrated, so its per-process usage appears in the Shared column instead of VRAM. A missing driver version is read from the adapter's PnP registry entry.
- Linux, containers and WSL Native Linux reads NVIDIA through NVML, AMD through sysfs and DRM fdinfo with no ROCm needed, and Intel
i915through DRM fdinfo, with some Intel readings requiring root. In Docker or Kubernetes containers it pairs NVML host PIDs with container processes and marks rows*or?. Under WSL it starts onepowershell.exeto stream Windows GPU counters and matches the WSL VM's GPU contexts to Linux processes;--no-hostturns this off. - macOS on Apple Silicon On Apple Silicon Macs the header shows allocated GPU memory and device utilization, and per-process GPU% comes from each Metal client's accumulated GPU time. Per-process memory comes from
footprintand needssudofor other users' processes. The Shared and Paged columns, clocks, power and temperature are not available, and Metal does not split work into 3D, compute, copy or video engines. - Installation from PyPI
uv tool install gputaskmanorpipx install gputaskmaninstalls the tool in an isolated environment on Windows, Linux, WSL and macOS with Python 3.11 or newer. Bothgputaskmanand the shortergtmcommand are installed, and upgrades useuv tool upgradeorpipx upgrade. - Portable builds and Nix flake Each tagged release publishes
gputaskman-VERSION-windows-x64.zip,windows-arm64.zip,linux-x64.tar.gzandlinux-arm64.tar.gzwith SHA-256 files, built by GitHub Actions with PyInstaller. The archives do not bundle GPU driver libraries, inference servers or models. NixOS users can runnix run github:shanselman/gputaskman; the flake was contributed and checked on x86_64 NixOS 26.05 and is not built in CI. - Privacy model The monitor reads local process metadata, model headers, load logs and local server responses. The README states that it does not dump model weights, send telemetry or read model names out of another process's memory. Model-path scanning skips API-key and key-file arguments and protected paths, and on macOS it skips other apps' sandbox containers.
Where gputaskman fits
Breaking down local LLM memory
With llama-server, Ollama or another GGUF runtime running, the selected process's inspector shows weights, KV cache and compute buffers next to the measured VRAM. Exact buffer sizes come from compatible load logs, for example a llama-server started with --log-file and verbosity 4; without logs the split is estimated from GGUF metadata and the context size. The README lists spot checks against llama.cpp b12061 where GGUF estimates for Qwen3-0.6B weights and KV cache matched the runtime log, and notes that sliding-window attention models such as Gemma 3 make the KV estimate an upper bound.
Measuring the effect of a context-length change
The documented workflow saves gputaskman --json > before.json, loads the model or restarts the server with a different -c value and sends one request, then saves after.json and runs gputaskman diff. The diff lists measured device and process changes separately from runtime-reported segments and estimates. The README gives an example where a Gemma 3 server's estimated KV growth was +504 MB while measured dedicated memory grew by +83 MB.
Explaining Windows desktop GPU usage
On a Windows desktop the table separates the Desktop Window Manager, browser processes, terminal and other apps, and the compositor row explains that Windows' Dedicated Usage counter counts every surface it can see. gputaskman prefers the Local Usage and Non Local Usage counters to avoid double counting, and when row sums exceed the adapter total the VRAM bar is normalized while labels stay raw. The ? key opens a built-in explanation of which counters are measured, inferred or unavailable.
Attributing GPU memory inside WSL and containers
Inside WSL, nvidia-smi lists no processes, so gputaskman reads the Windows host counters through interop, shows the WSL VM total from vmwp.exe and lists Windows apps as W: rows. In Docker, Kubernetes or rented GPU containers it pairs NVML host PIDs with container processes that have libcuda.so mapped. Rows marked * are matched and rows marked ? are heuristic guesses, and the inspector and JSON state which kind each row is.
Logging a long-running GPU job
For a training run, an overnight inference server or a game session, gputaskman record writes one JSON snapshot per interval to a JSON Lines file. Any two lines can be extracted and passed to gputaskman diff, for example the first and last sample. Replaying or summarizing a whole recording is listed under future work in the README roadmap.
Checking speech and AI desktop apps
For desktop AI apps that read a model and close the file, such as whisper-style speech tools, gputaskman shows observable runtime DLLs, VRAM and engine activity, installed model candidates for recognized AI runtimes and, since v0.4.1, model-like files passed as launch arguments, labelled path-arg and not proven loaded. The Handy speech app has a dedicated adapter that reads its selected model and load events from its local log, which the README describes as historical evidence rather than proof of current residency. Opt-in ETW file-open tracing to name such models is listed as planned. Speech apps listed on iThub include Handy, and local runtimes include Ollama and llama.cpp.
Install
uv tool install gputaskmanReviews of gputaskman
Be the first to share your experience with gputaskman.
Write a review
Loading review form…
Alternatives to gputaskman
 ArgusArgus is an AGPL-3.0 task manager for Windows 10 22H2 and Windows 11 x64, written in Rust with GPUI Kit. It covers processes, performance and SMART data, services, startup apps, TCP/UDP connections, file locks and 7 days of resource history.
 MoleMole is a free GPL-3.0 command-line toolkit (mo) for cleaning caches, removing apps with their leftovers, purging build artifacts, exploring disk usage and watching live system status on macOS, with separate Windows and early Linux CLIs.
 HandyHandy is a free, MIT-licensed speech-to-text app for Windows, macOS and Linux. Press a shortcut, speak, and a local Whisper, Parakeet or other model transcribes the audio and pastes the text into the focused field, without a cloud service.