

What is OpenObserve?
OpenObserve, also called O2, is an observability platform for logs, metrics, traces, real user monitoring (RUM) with session replay, dashboards, alerts, incidents, ingest pipelines and AI or LLM observability. It is developed by OpenObserve Inc., which states on its about page that it was founded in 2022 and lists an address in Menlo Park, California. The server is written in Rust and ships as a single binary; the web interface is built with Vue and ECharts. The README describes a storage layer based on Parquet columnar files on S3-compatible object storage, with partitioning, indexing and caching, native multi-tenancy through organizations and streams, and a stateless node design.
There are two editions. The open-source edition is licensed under AGPL-3.0 and is free without ingestion limits. The Enterprise edition is distributed under a commercial license, is free to self-host up to 50 GB of ingestion per day and adds single sign-on (OIDC, OAuth, SAML 2.0, LDAP and Active Directory), role-based access control with custom roles, a 365-day immutable audit trail, federated search across clusters (Super Cluster), sensitive data redaction, query and workload management and contractual support, according to the downloads and edition comparison page. A hosted service, OpenObserve Cloud, is billed by usage.
A single node runs from one container or binary and stores data on local disk or object storage. The Docker quickstart uses the public.ecr.aws/zinclabs/openobserve image on port 5080 with a root user email and password set through environment variables. For larger installations, the high availability guide describes a Helm-based Kubernetes deployment from charts.openobserve.ai with router, ingester, querier, compactor and scheduler components, NATS for cluster coordination, PostgreSQL (or MySQL) for metadata, OpenFGA for authorization and mandatory object storage such as Amazon S3, MinIO, RustFS, GCS or OpenStack Swift. Binaries are published for Linux (amd64, arm64 and musl builds), Windows (amd64) and macOS on Apple Silicon.
The latest GitHub release is v1.2.0-rc1, a release candidate published on November 4, 2026, with metrics v2 work (alerts from charts, compare, forecast and formulas), PromQL alignment with Prometheus and many alerting fixes. The most recent stable line is v1.1, whose v1.1.0 notes (October 14, 2026) list Prometheus-compatible PromQL, Service Graph v4, trace triage with critical path and latency heatmaps, public status pages built on synthetic checks and a managed prompt registry for AI observability. The README states that ingested data is immutable: it cannot be modified or deleted individually, only dropped by retention period.
The README lists SOC 2 Type II and ISO 27001 certification, GDPR compliance and HIPAA readiness with a BAA under Enterprise contracts. Community support runs through Slack and GitHub Discussions. Similar platforms on iThub include SigNoz, Grafana, Parseable and Datadog.
OpenObserve screenshots
Explore the interface. Open a screenshot to view it at full size.
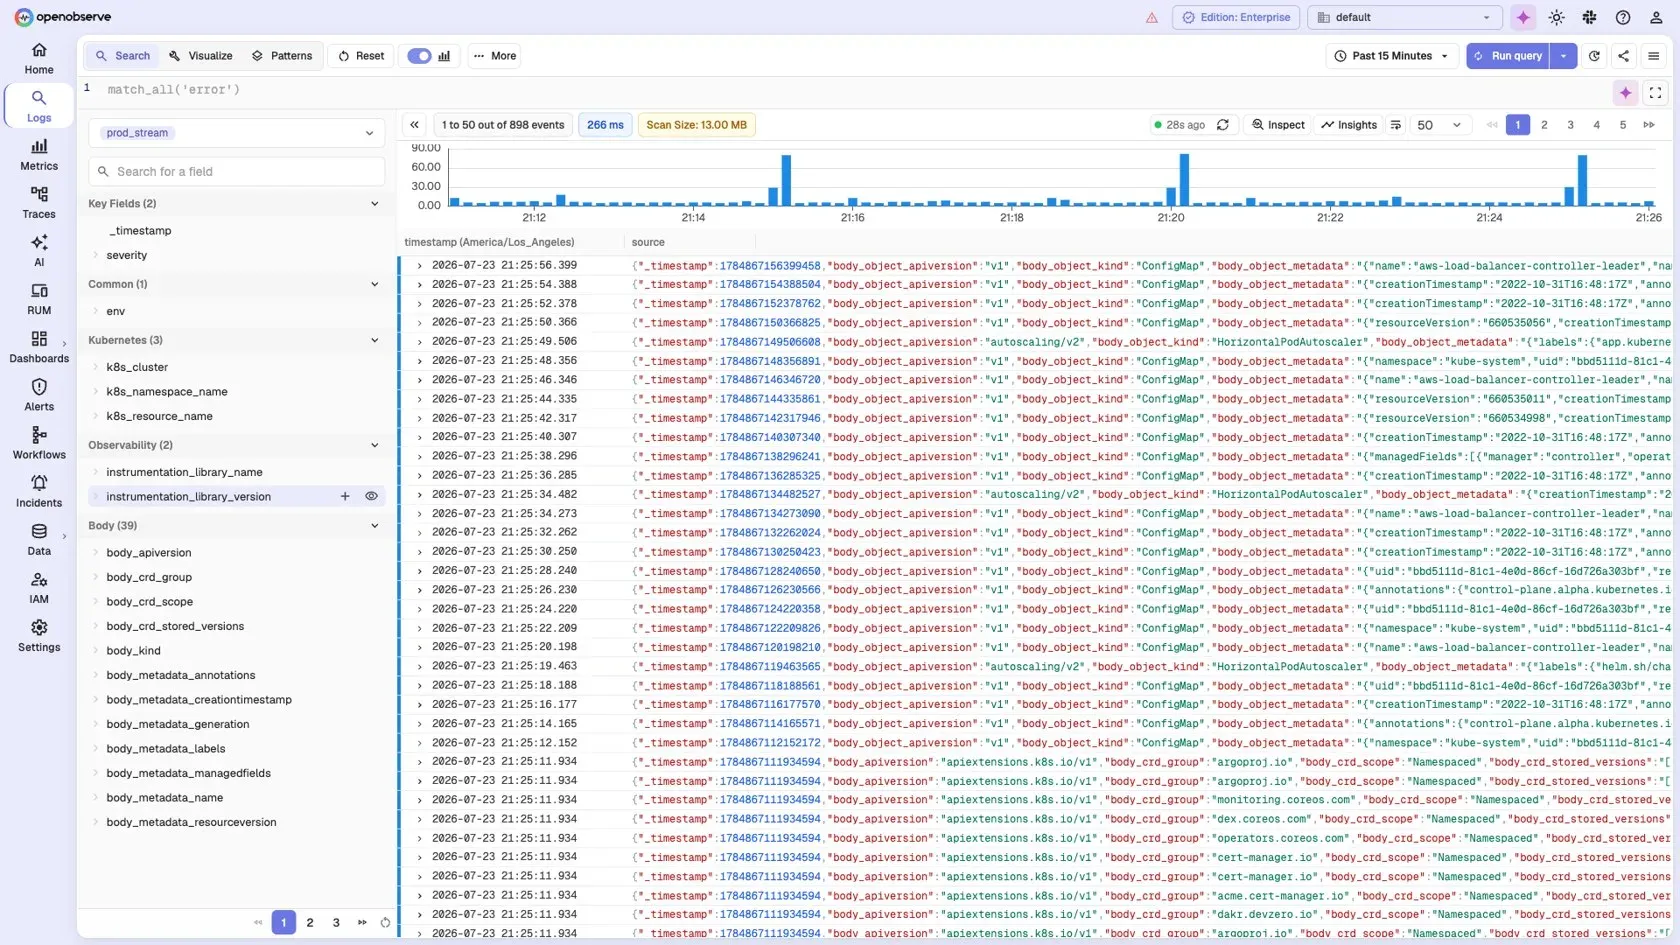
Log search with a query, event histogram, field explorer and Kubernetes log records.
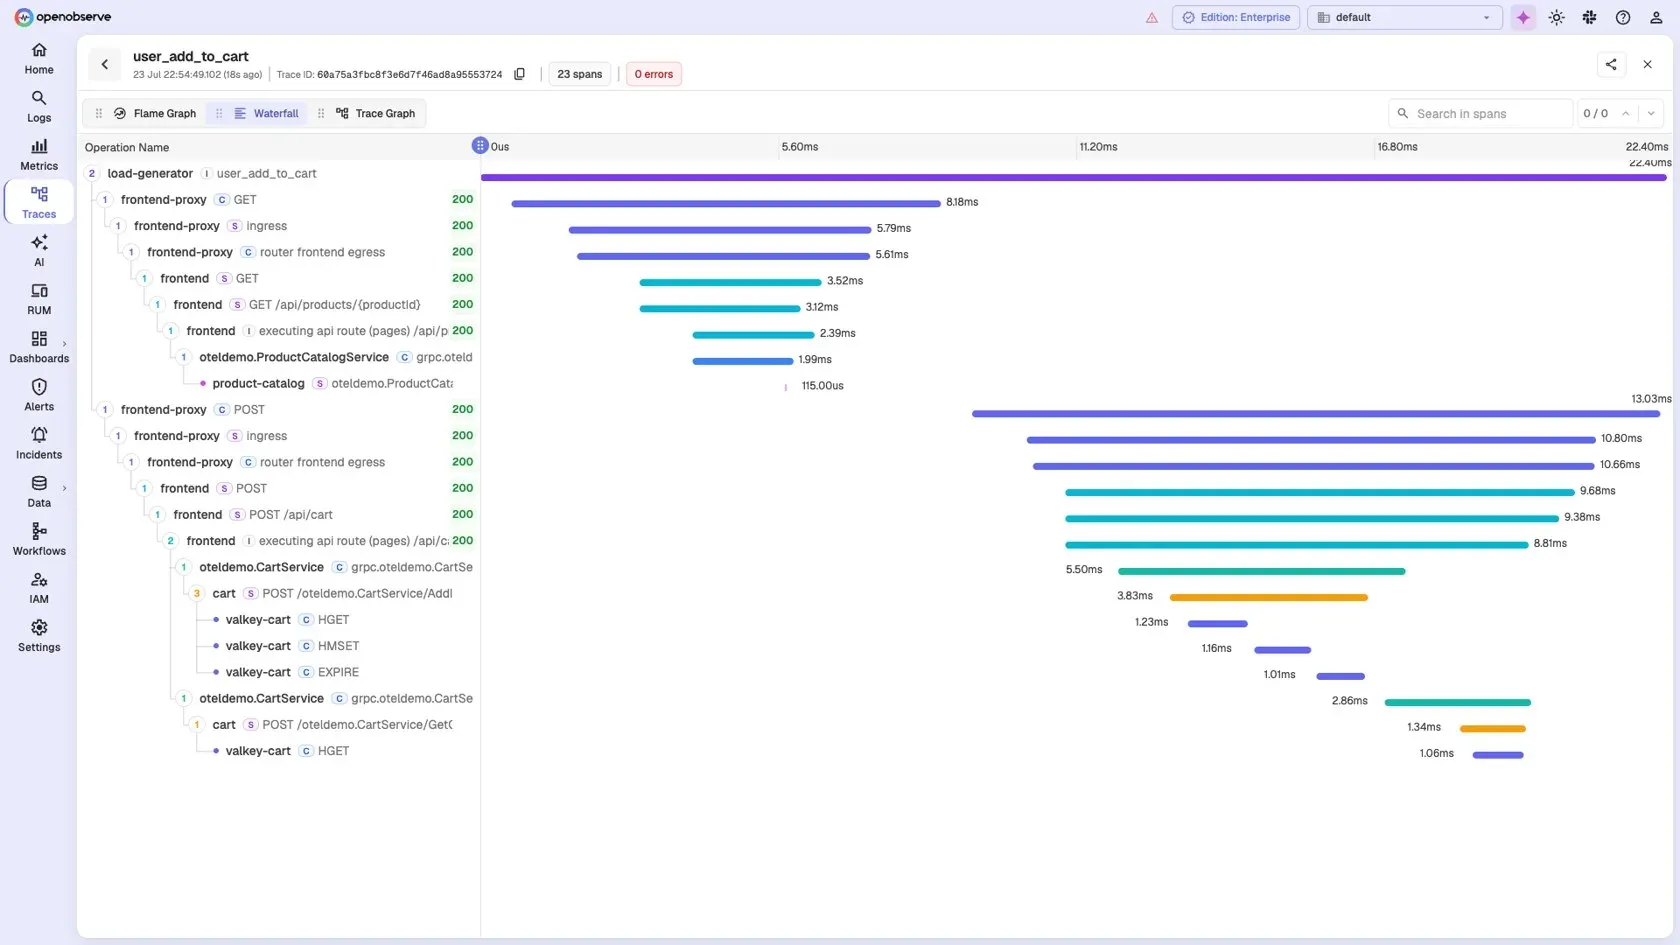
Trace waterfall for an OpenTelemetry demo request across frontend, cart and Valkey spans.
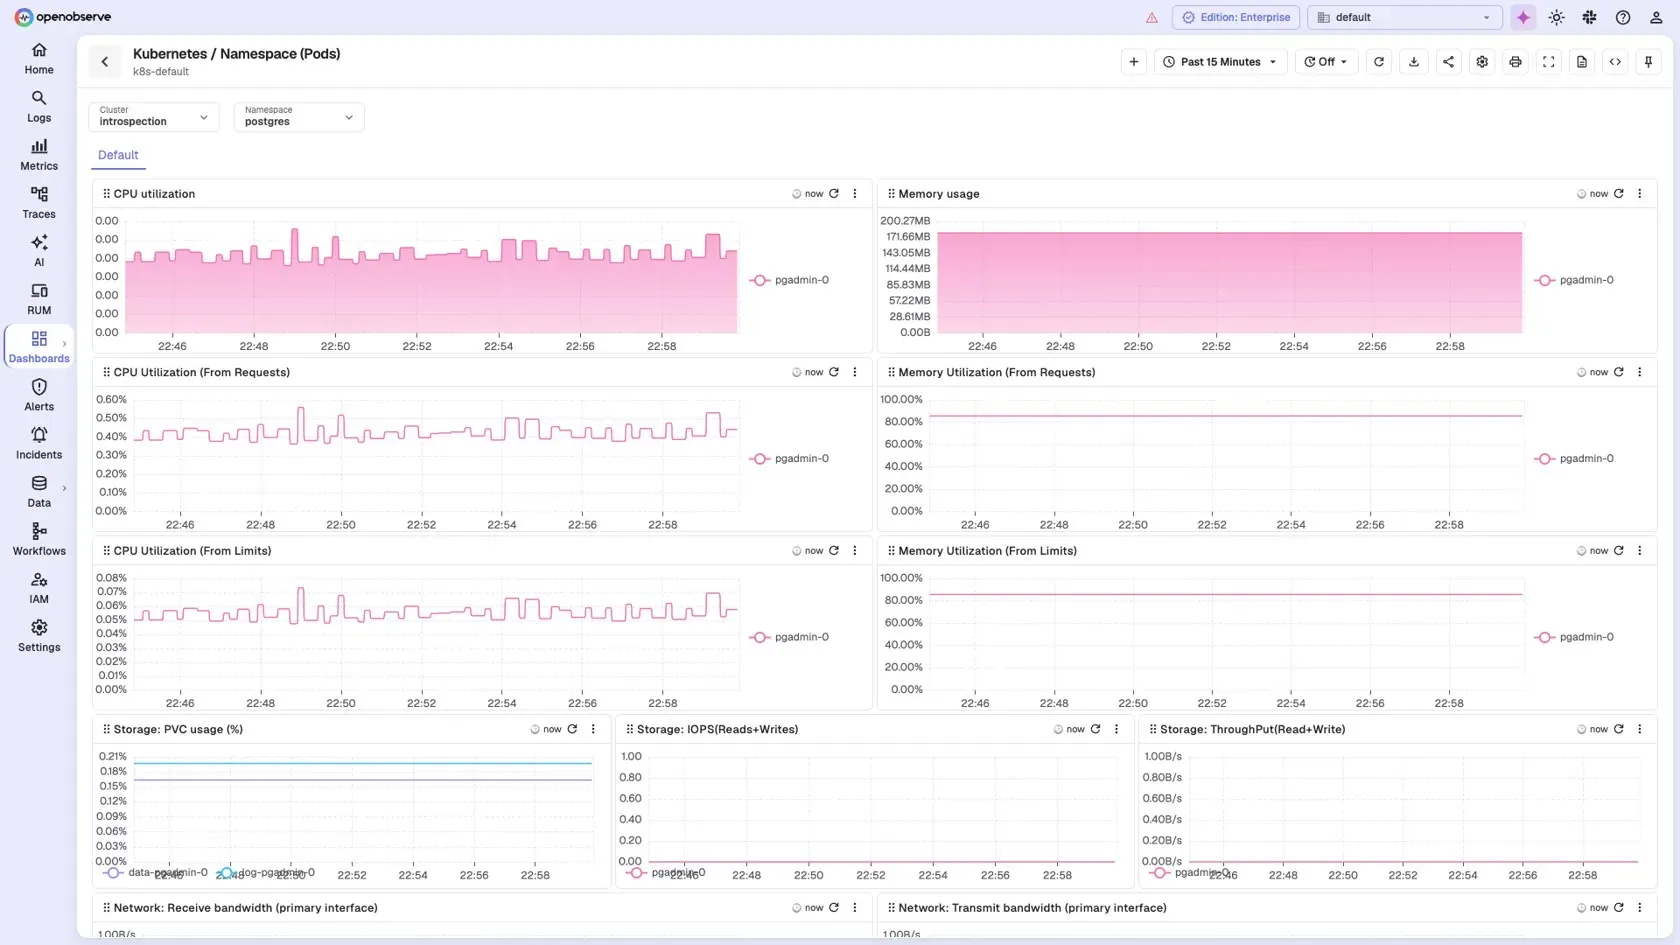
Kubernetes namespace dashboard with cluster and namespace variables and CPU, memory and storage panels.
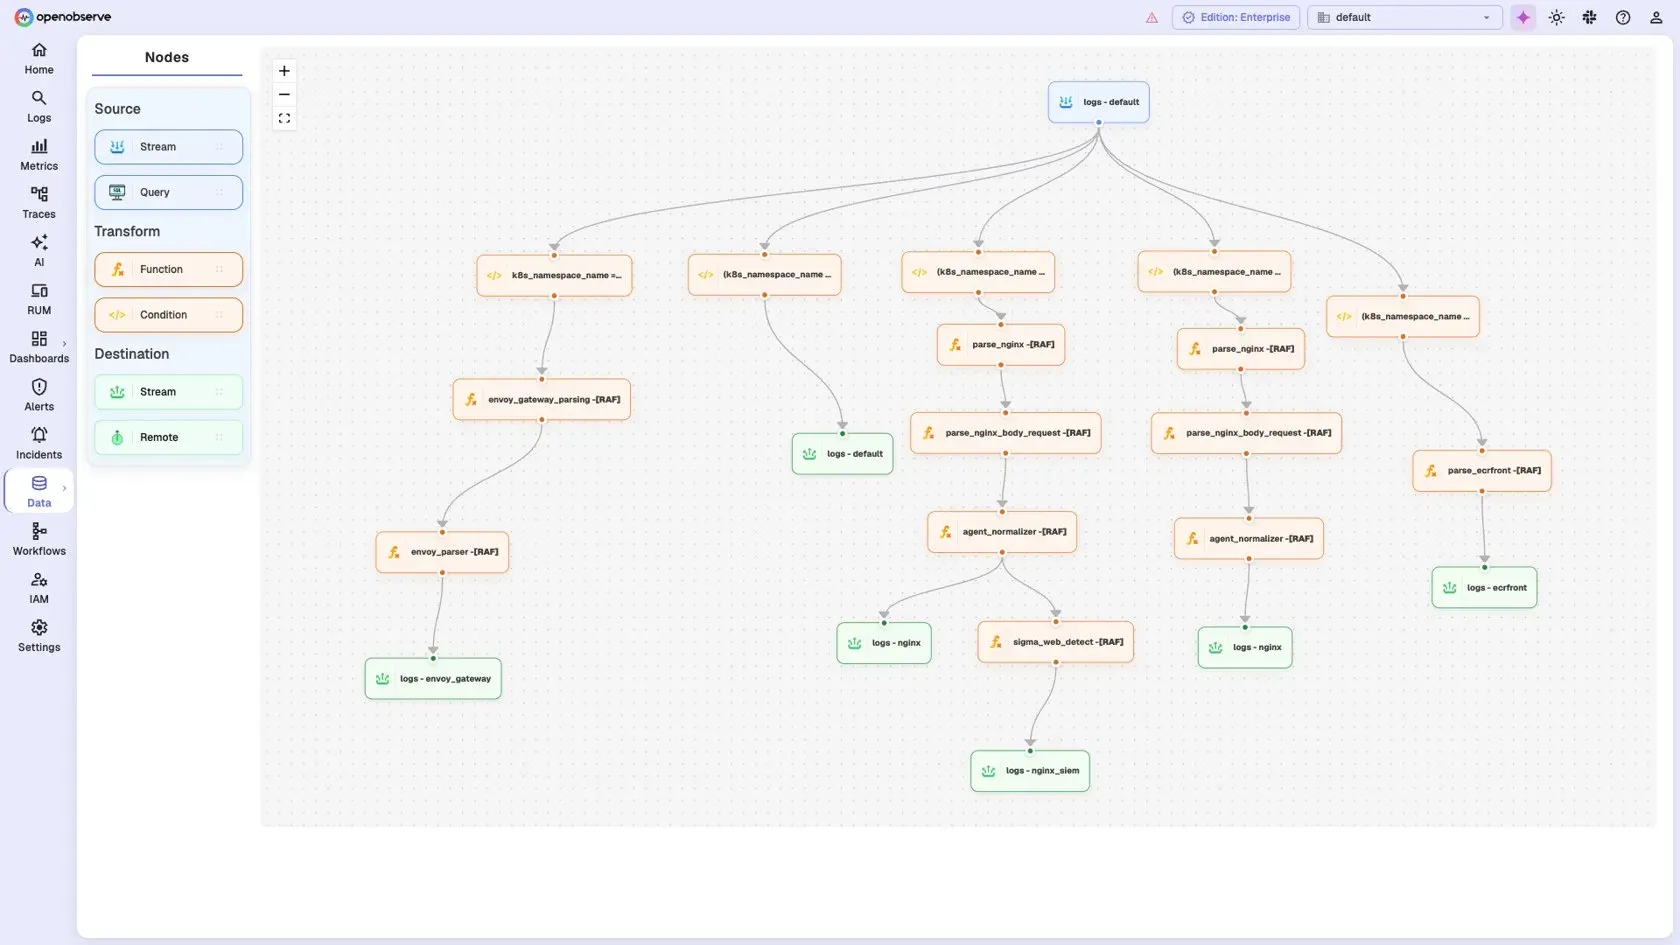
Visual pipeline editor routing a log stream through functions and conditions into destination streams.
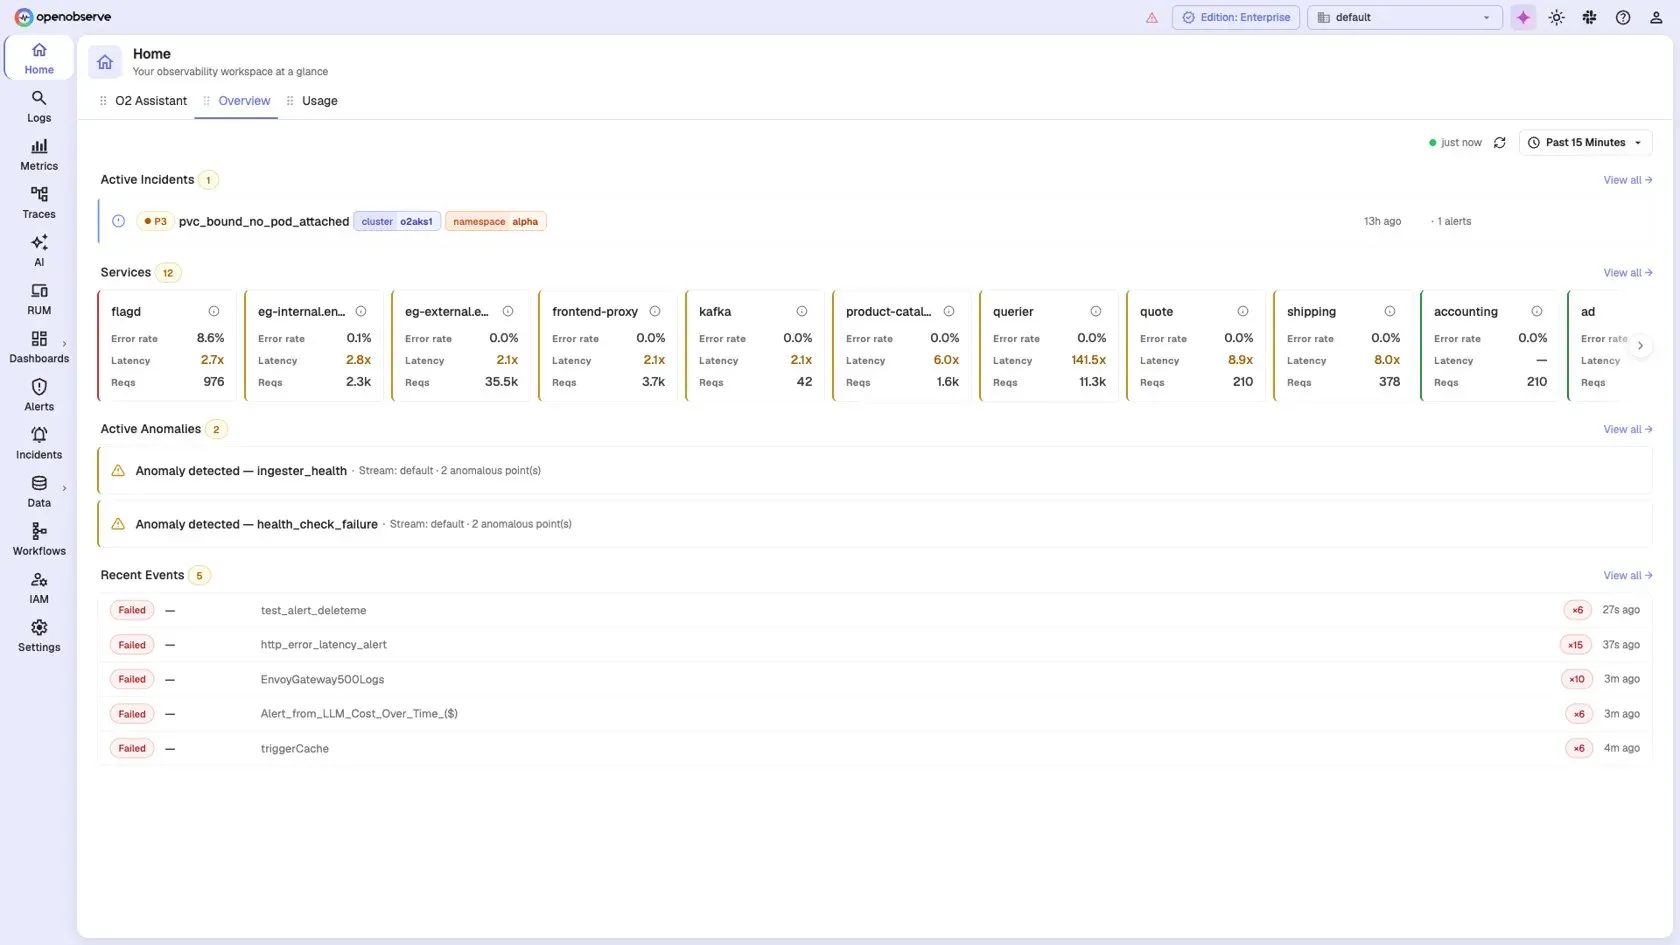
Home overview with active incidents, service error rates and latency, anomalies and recent events.
Source: official OpenObserve project page.
Key capabilities
- Log search Logs are queried with full-text search or SQL, with quick filters, a field explorer, a histogram and a visual query builder. Results can be turned into dashboards and alerts, as described on the logs page.
- Metrics with SQL and PromQL Metrics are queried with SQL or PromQL, browsed with faceted filters and combined with formulae. Since v1.1.0, PromQL subqueries, the @ modifier, vector matching and set operators return the same results as Prometheus, and exemplars on charts link to matching traces.
- Distributed tracing OpenTelemetry traces are shown as waterfalls, flame graphs and trace graphs, with span search. v1.1.0 added critical path analysis, RED insights, span percentiles and a latency heatmap that drills down to individual traces.
- Service graph A service graph visualizes dependencies between services with per-edge request counts and health coloring. Service Graph v4 in v1.1.0 also shows AI agent relationships.
- Dashboards Dashboards are built from any signal with a drag-and-drop panel builder, template variables and geo maps; the README lists 19 or more chart types.
- Frontend monitoring (RUM) The browser RUM SDK records Core Web Vitals, errors, performance data and full session replay with an event timeline. The repository description lists RUM for web, Android and iOS.
- Alerts and incidents Scheduled and real-time alerts on logs, metrics or traces use thresholds and anomaly detection with tunable value bands, and send to configurable destinations. Related alerts are grouped into incidents with open, acknowledged and resolved states.
- Ingest pipelines A visual pipeline editor connects source streams or queries to transform nodes (VRL functions and conditions) and destination streams or remote destinations, for enrichment, redaction, reduction and logs-to-metrics conversion. Remote destinations are part of the Enterprise edition.
- AI and LLM observability GenAI applications are monitored by cost, tokens, latency percentiles and error rates per model, with agent graphs, session traces, evaluation scoring and, since v1.1.0, a managed prompt registry.
- O2 AI Assistant An in-product assistant writes SQL, VRL and PromQL from natural-language questions and creates queries, dashboards and alerts. The v1.1.0 notes state that paid AI features on Cloud require explicit opt-in by the organization.
- Synthetics and status pages Synthetic checks run against endpoints with shared variables and environments, and public status pages can be published from them. Custom domains and notices on status pages are Enterprise features.
- Ingestion sources The ingestion documentation covers the OpenTelemetry Collector, Vector, Filebeat, Fluent Bit, Fluentd, Amazon Kinesis Firehose, Splunk HEC, syslog alternatives, Prometheus and Telegraf, plus HTTP APIs
_json,_multiand_bulk. Continuous profiling data is accepted over OTLP and from Java, Go, Rust and eBPF profilers. - Storage and retention Data is stored as Parquet files on local disk or S3-compatible object storage. Ingested records are immutable and are removed only through retention settings.
- Multi-tenancy and access control Organizations and streams isolate data. In the open-source edition all users have full access; role-based access control, custom roles, user groups, role-scoped service account tokens and SSO are Enterprise features that require HA mode.
- Single-node install The quickstart starts OpenObserve with one
docker runcommand or a downloaded binary, with the UI on port 5080. AdownloadO2.shscript is provided for Linux and macOS. - High availability on Kubernetes HA mode is installed with the official Helm chart and uses NATS, PostgreSQL through the CloudNativePG operator, OpenFGA and object storage. Local disk storage is not supported in HA mode.
- OpenObserve Cloud The pricing page lists Cloud Professional at $0.50 per GB ingested and $0.01 per GB queried, with 15 months of metrics retention, 30 days for other data, extended retention at $0.02 per GB per 30 days, unlimited users and a 14-day trial. Cloud Enterprise has custom pricing and bring-your-own-bucket options.
- API Ingestion, search and management operations are available over an HTTP API documented in the API reference, alongside the OTLP and Prometheus-compatible endpoints.
Where OpenObserve fits
Centralized log management
Log shippers such as Fluent Bit, Vector, Filebeat or the OpenTelemetry Collector send logs from servers and Kubernetes clusters into streams. Engineers search with full-text queries or SQL, filter by fields such as namespace or severity, and save searches as dashboard panels or alerts. Retention settings per stream decide how long the Parquet data is kept on disk or in the object storage bucket.
Kubernetes and infrastructure metrics
Prometheus remote write, Telegraf or the OpenTelemetry Collector deliver metrics that are queried with PromQL or SQL. The README shows a Kubernetes namespace dashboard with cluster and namespace variables, CPU and memory utilization panels and storage throughput charts.
Application performance and tracing
Services instrumented with OpenTelemetry SDKs send traces over OTLP. Teams follow a request through the waterfall or flame graph, inspect slow spans, compare latency percentiles and use the service graph to see which dependency is degraded. Exemplars on metric charts link back to individual traces.
Frontend and user experience monitoring
The RUM SDK in a web application collects Core Web Vitals, JavaScript errors and session replays, so a reported problem can be replayed with its event timeline and correlated with backend traces, as described on the frontend monitoring page.
Data processing at ingest
Pipelines parse raw log formats, redact sensitive fields, drop noisy records and convert logs into metrics before storage. The README's pipeline example routes a default log stream through parsing and normalization functions into separate nginx, envoy and SIEM streams.
Monitoring LLM applications
Applications that call language models send OpenTelemetry GenAI traces. The AI observability views report token usage, cost, latency and errors per model, show agent graphs and session traces, and score outputs with evaluators, with prompts versioned in the prompt registry.
Reviews of OpenObserve
Be the first to share your experience with OpenObserve.
Write a review
Loading review form…
Alternatives to OpenObserve
 SigNozSigNoz is an open-source observability platform on OpenTelemetry with logs, metrics, traces and alerts, self-hosted free or on SigNoz Cloud from $49.
 GrafanaGrafana is the open source visualization and alerting server from Grafana Labs. It queries Prometheus, Loki, Elasticsearch, InfluxDB, PostgreSQL and other data sources in place, and runs self-managed on Linux, Windows, macOS, Docker or Kubernetes, or as Grafana Cloud.
 DatadogDatadog is a SaaS observability and security platform that collects metrics, traces, logs and events through its open-source Agent and 1,000+ integrations, with per-host and per-volume pricing across regional sites.