
What is colibri?
colibri is a free, open-source inference engine written in pure C, with one file per model family, that runs very large open models on the machine you already have. A mixture-of-experts model is huge on disk and small per token, so colibri keeps the dense part (attention, shared experts, embeddings) in RAM, reads the routed experts from disk when the model asks for them, and uses a cache that learns which experts your work uses. A GPU is optional. It is licensed under Apache-2.0.
The README lists thirteen engines, covering language models from several families as well as an image model and decision models. The language models also run from published GGUF files, on the CPU, on any GPU through Vulkan and on NVIDIA cards through CUDA. The setup script inspects RAM, disk, CPU and GPUs, recommends a model that fits, builds or downloads the engine, downloads the model with resume, and starts colibri with a browser dashboard.
Applications can connect through an OpenAI-compatible base URL and an Anthropic-compatible one on the local port, and assistants that speak the Model Context Protocol can use its MCP server. The project also describes itself as an open research platform, and its default policy never silently changes model precision or router semantics. The smallest model needs 22 GB of free disk.
colibri screenshots
Explore the interface. Open a screenshot to view it at full size.
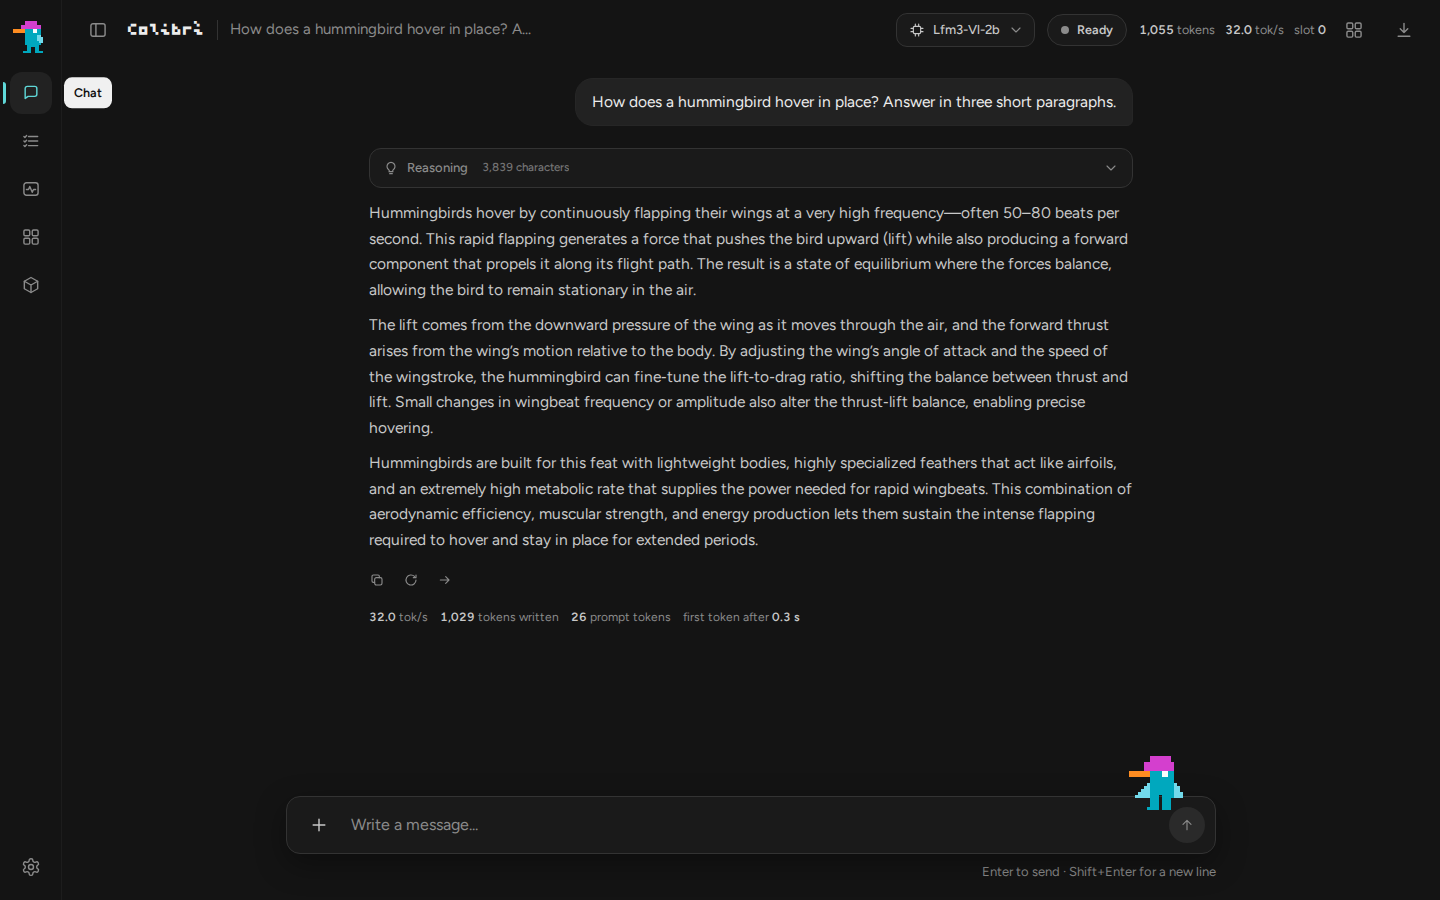
Source: official colibri project page.
Key capabilities
- Tiered placement Dense weights in RAM, hot experts cached, the rest streamed from disk.
- Guided setup Checks your hardware, recommends a model and resumes interrupted downloads.
- GPU options CPU by default, with Vulkan for any GPU and CUDA for NVIDIA cards.
- Dashboard A browser view that shows every expert as it fires.
- Compatible endpoints OpenAI-style and Anthropic-style local base URLs.
- MCP server Tools to detect hardware, recommend, install, start, stop and check.
Where colibri fits
- Running large MoE models on modest hardware
- Disk-backed expert streaming and caching
- Local OpenAI- and Anthropic-style APIs
- Hardware detection and model recommendation
- Inference research and measurement
Reviews of colibri
Be the first to share your experience with colibri.
Write a review
Loading review form…
Alternatives to colibri
 DwarfStarDwarfStar runs selected DeepSeek, GLM and Qwen models locally, with a conversational CLI, a native coding agent and an HTTP server. It targets specific Metal, CUDA and ROCm hardware configurations.
 FreeTokenFreeToken is an Apache-2.0 serving engine for open-weight MoE models on consumer hardware, with a Windows and Linux desktop app, a CLI and compatible APIs.NNeedleNeedle is an on-device model from Cactus Compute for tool calling, schema-constrained extraction and local embeddings on resource-constrained devices.