

What is FreeToken?
FreeToken is an edge-native Mixture-of-Experts serving engine, licensed under Apache 2.0, designed for running frontier-scale open-weight models on personal and consumer hardware. It treats GPUs, CPUs, host memory and interconnects as one elastic inference platform. The README lists native support for NVIDIA RTX 30, RTX 40 and RTX 50 series GPUs, across laptops, gaming desktops and workstation GPUs.
Its runtime combines bandwidth-adaptive CPU and GPU co-execution, full-layer double-buffered prefill streaming and global LRU expert caching. Semantic anchor checkpoints for recurrent state and KV caches let agentic context edits, such as tool calls and thinking blocks, avoid redundant context recomputation. VRAM can be re-allocated between expert caches and KV memory at runtime without restarting the engine or reloading weights.
There are two ways to get started. A desktop app for Windows or Linux is available from flashml.ai and sets the engine up with a GUI for running models, chatting and tuning. The command line version installs with uv or pip, or can be built from source. Anthropic- and OpenAI-compatible APIs support coding and tool-calling agents. Supported models, quantization formats and checkpoint conversion are documented in the repository.
FreeToken screenshots
Explore the interface. Open a screenshot to view it at full size.
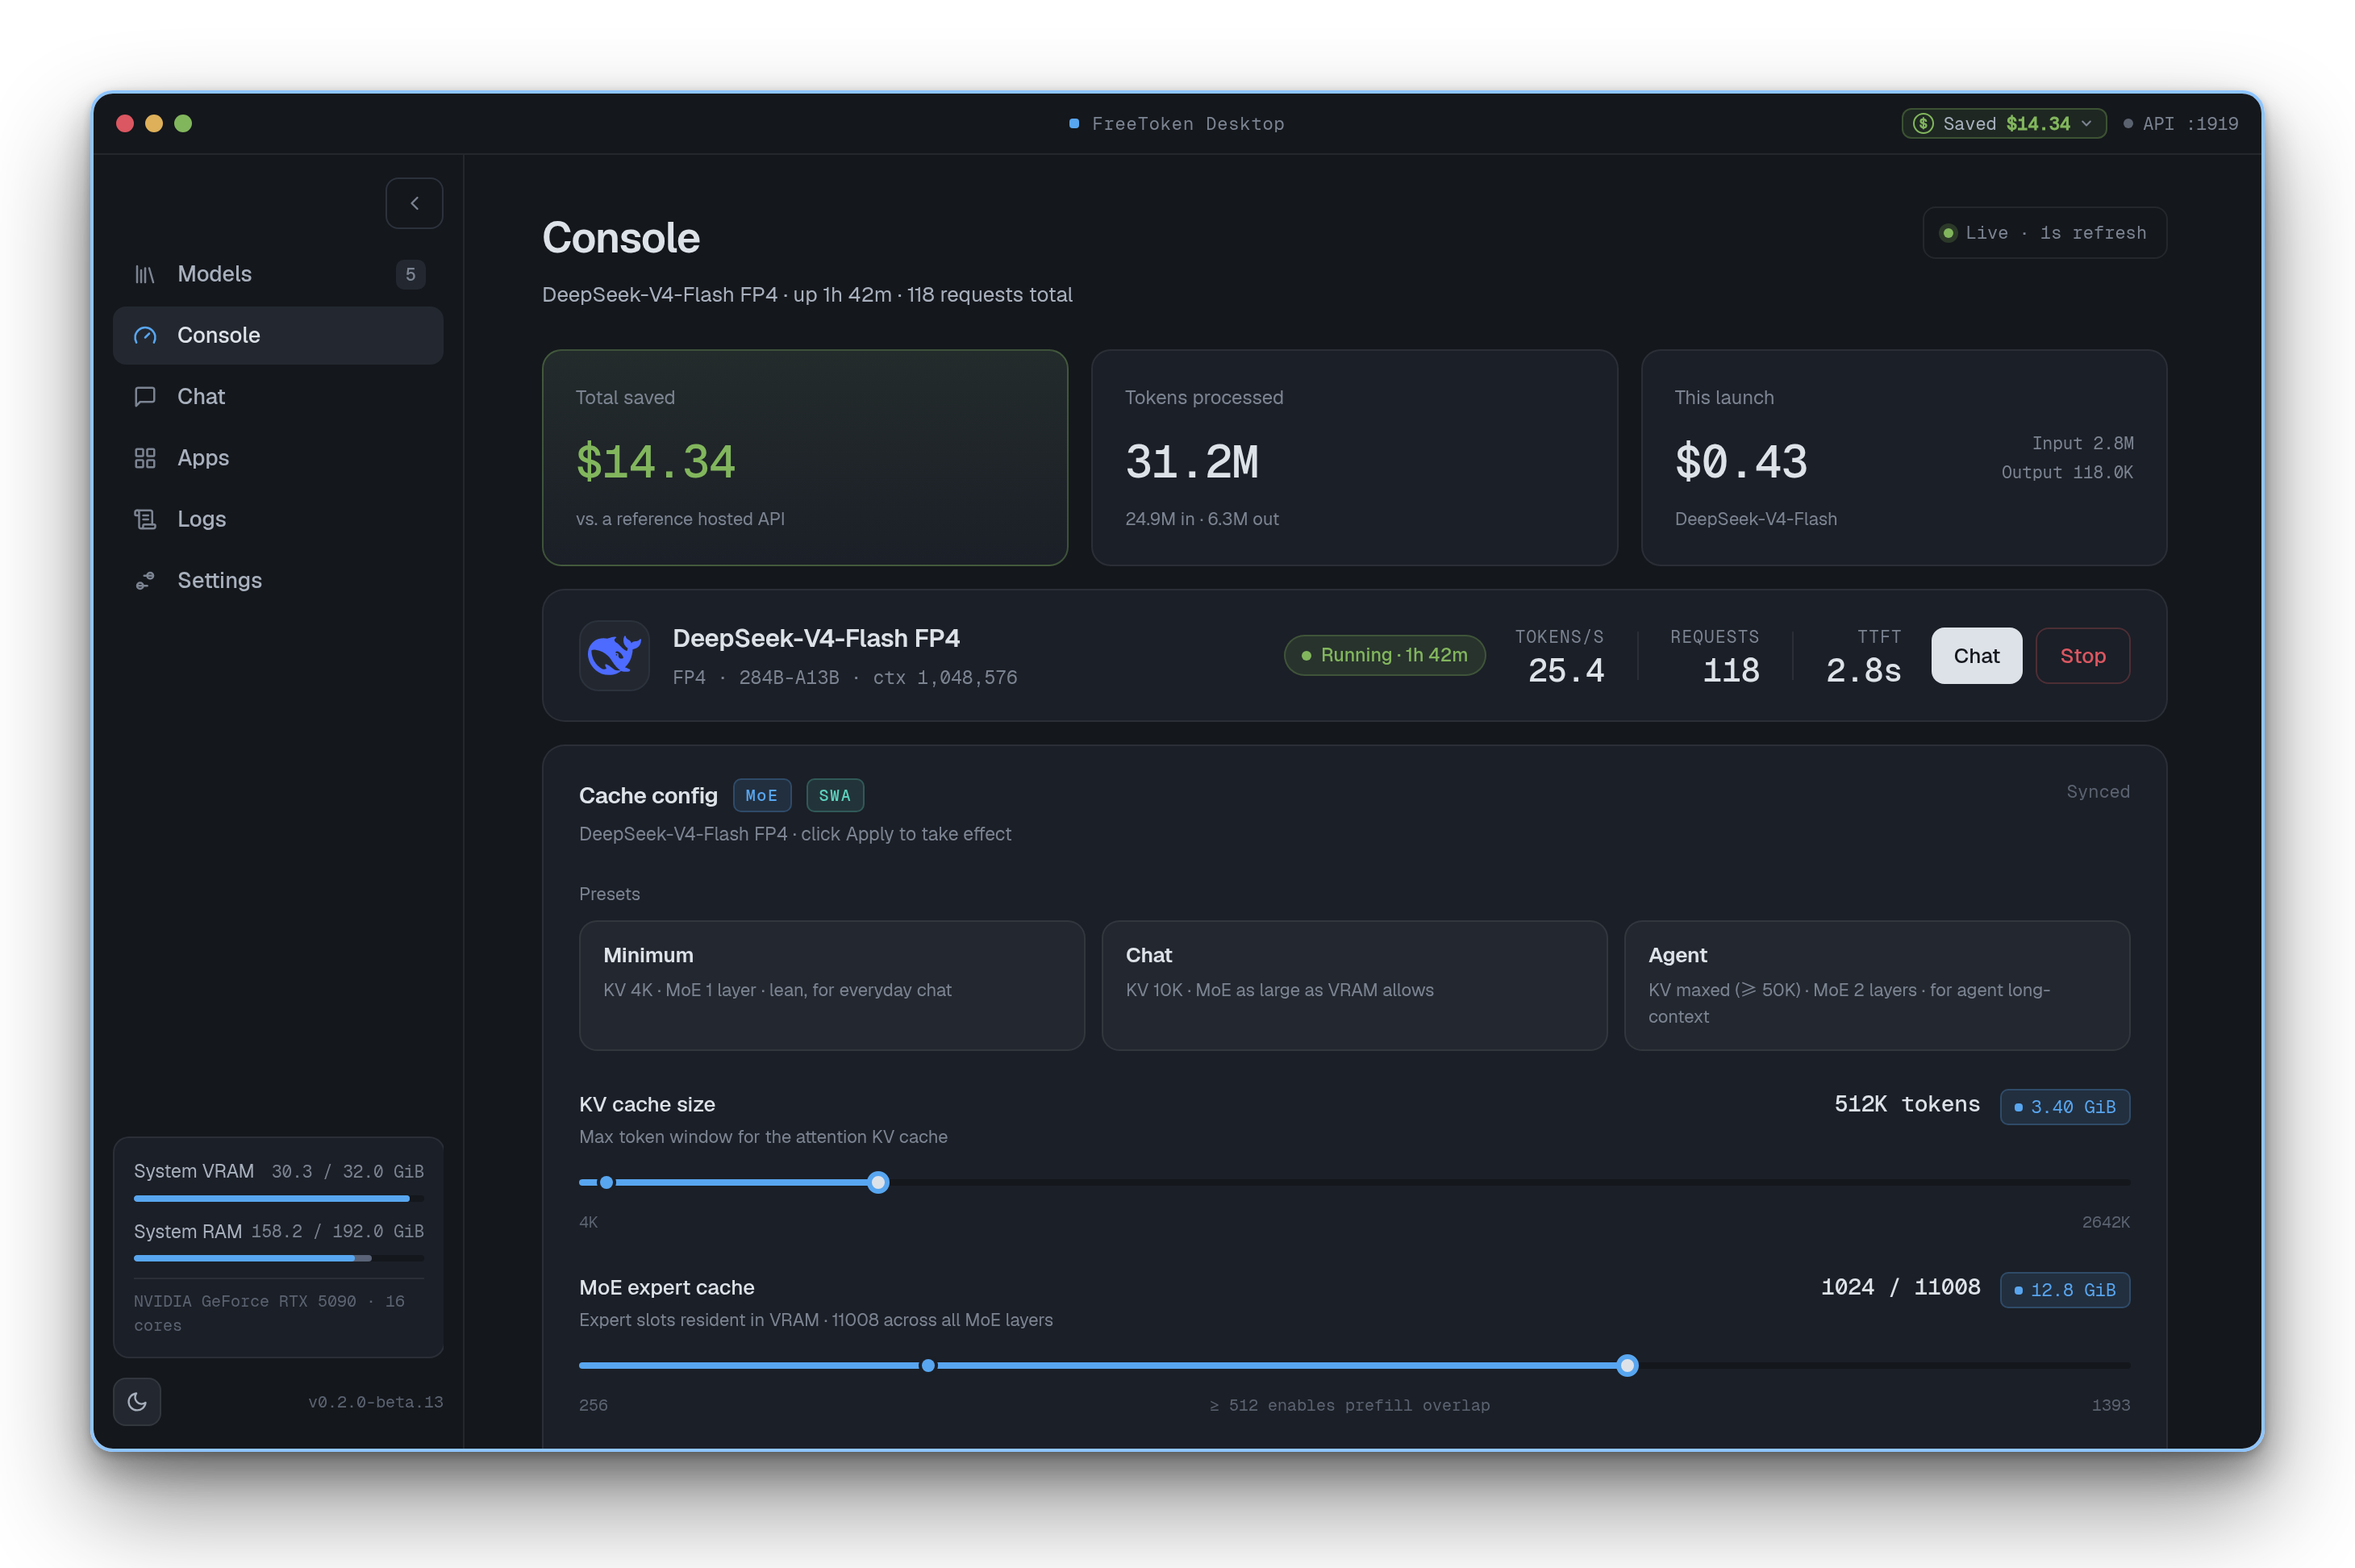
Source: official FreeToken project page.
Key capabilities
- Edge MoE runtime CPU and GPU co-execution with prefill streaming and expert caching.
- Context reuse Checkpoints that avoid recomputing context after agentic edits.
- Elastic memory VRAM moved between expert caches and KV memory without a restart.
- Compatible APIs Anthropic and OpenAI interfaces for coding and tool-calling agents.
- Desktop app A GUI for running models, chatting and tuning, for Windows and Linux.
- CLI Install with uv or pip, or build from source.
Where FreeToken fits
- MoE on consumer GPUs FreeToken is an edge-native Mixture-of-Experts serving engine for running open-weight models on personal and consumer hardware, with native support for NVIDIA RTX 30, 40 and 50 series GPUs.
- CPU and GPU co-execution Bandwidth-adaptive CPU and GPU co-execution is part of the runtime, alongside prefill streaming.
- Expert and context caching A global LRU expert cache and semantic anchor checkpoints for recurrent state and KV caches avoid redundant context recomputation.
- Runtime memory re-allocation VRAM moves between expert caches and KV memory without engine restarts or weight reloading.
- Agent-compatible APIs Ft serve starts an API server with OpenAI, Anthropic and Responses endpoints for agents such as Codex, Claude Code and OpenCode.
- Desktop and CLI A desktop app for Windows or Linux provides a GUI, and the CLI installs with uv or pip.
- Bandwidth benchmark Ft bench bw benchmarks CPU against PCIe bandwidth to calibrate hybrid MoE decode.
Install
uv pip install "freetoken[accel]"Reviews of FreeToken
Be the first to share your experience with FreeToken.
Write a review
Loading review form…
Alternatives to FreeToken
 DwarfStarDwarfStar runs selected DeepSeek, GLM and Qwen models locally, with a conversational CLI, a native coding agent and an HTTP server. It targets specific Metal, CUDA and ROCm hardware configurations.NNeedleNeedle is an on-device model from Cactus Compute for tool calling, schema-constrained extraction and local embeddings on resource-constrained devices.PMProject MayaProject Maya runs large mixture-of-experts models locally, spreading experts across GPU memory, RAM and SSD, with browser chat and OpenAI-compatible APIs.