

What is Uptrace?
Uptrace is an application performance monitoring (APM) and observability platform for distributed tracing, metrics and logs. It collects data through OpenTelemetry, stores telemetry in ClickHouse and keeps metadata such as users, projects, dashboards and monitors in PostgreSQL, with Redis used for caching and background jobs. The server is written in Go with a Vue.js user interface, and the source is published in the uptrace/uptrace repository under the GNU Affero General Public License v3.0.
Uptrace is offered in two forms. The self-hosted version runs as a single uptrace binary next to the three databases; the self-hosting overview lists Docker Compose, a Kubernetes Helm chart, an Ansible playbook and manual installation as deployment methods. Uptrace Cloud is the hosted service, billed by ingested data volume and run in Hetzner data centres in Germany with redundant backups in Finland. Self-hosted editions range from the free Community edition to paid Starter, Team, Business and Enterprise tiers, listed on the editions page.
The latest GitHub release is v2.1.0-rc.2, published on October 22, 2026, with DEB and RPM packages for amd64 and arm64 and standalone binaries for Linux, macOS (amd64 and arm64) and Windows amd64. The previous stable release is v2.0.3 from May 13, 2026. According to the changelog, the 2.1 line raises requirements to ClickHouse 26.3 or later, PostgreSQL 15 or later and Redis 6 or later, replaces the separate database commands with uptrace migrate up, blocks outbound requests to private addresses by default and requires a non-placeholder service.secret.
Version 2.1 also adds incidents that group related alerts, service level objectives with burn-rate rules, anomaly, outlier and forecast monitors for metrics, alert policies in place of alert rules, a Traces page with cross-join queries, full-text search over spans and logs, Sentry SDK ingestion, issue creation in GitHub or Forgejo, Prometheus remote write 2.0 and an MCP server for AI assistants. Upgrades are supported directly from v2.0.0 to v2.0.3 and from every v2.1 beta; upgrades from v1.x are not supported.
Uptrace does not ship its own instrumentation agents. Applications send data with OpenTelemetry SDKs or the OpenTelemetry Collector, and the documentation covers C++, .NET, Erlang and Elixir, Go, Java, JavaScript, PHP, Python, Ruby, Rust and Swift. Help is available through GitHub Discussions, Telegram and Slack. Other OpenTelemetry and ClickHouse based platforms listed on iThub include SigNoz, HyperDX and OpenObserve.
Key capabilities
- Single interface for traces, metrics and logs Spans, logs, errors and metrics are stored in the same ClickHouse database and explored in one UI. The 2.1 line reorganises the Tracing section as Explore, which also contains Metrics and Annotations, and adds a Traces page that filters whole traces. Global search opens with Cmd+K or Ctrl+K.
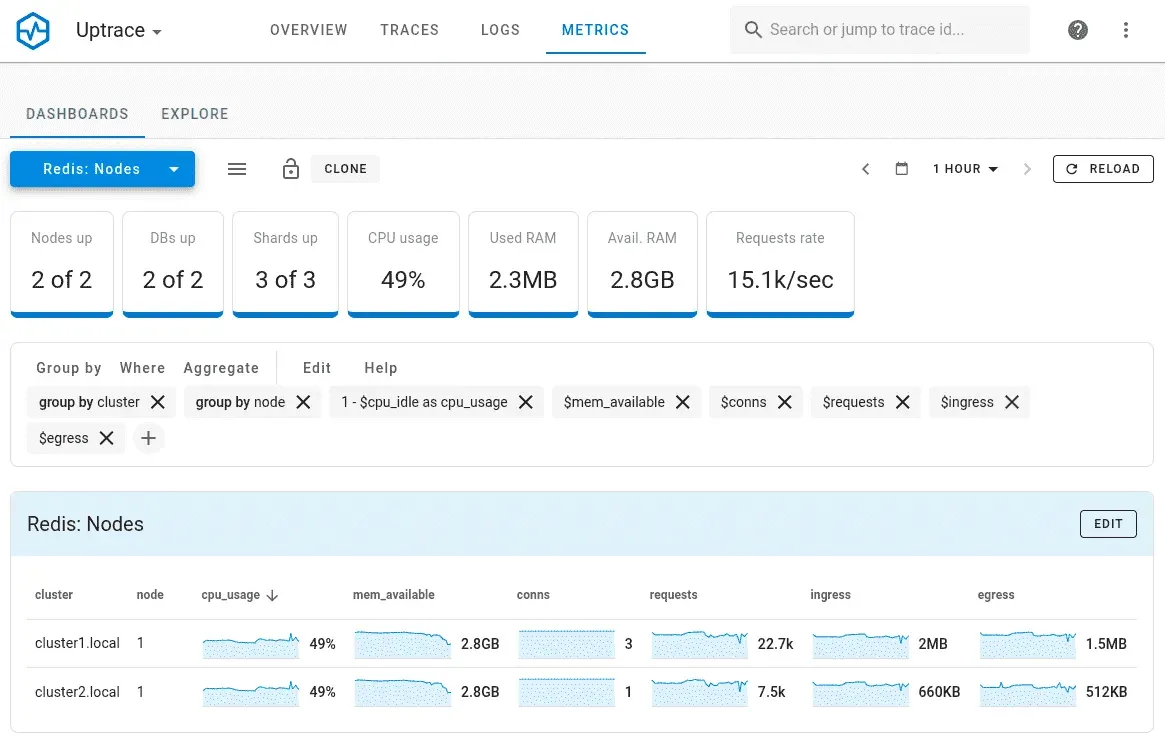
- Pre-built dashboards More than 50 dashboards are created automatically once matching metrics start arriving, for example for Redis, PostgreSQL or host metrics. Dashboards can be cloned and edited, and overview dashboards are suggested from available templates during project setup.
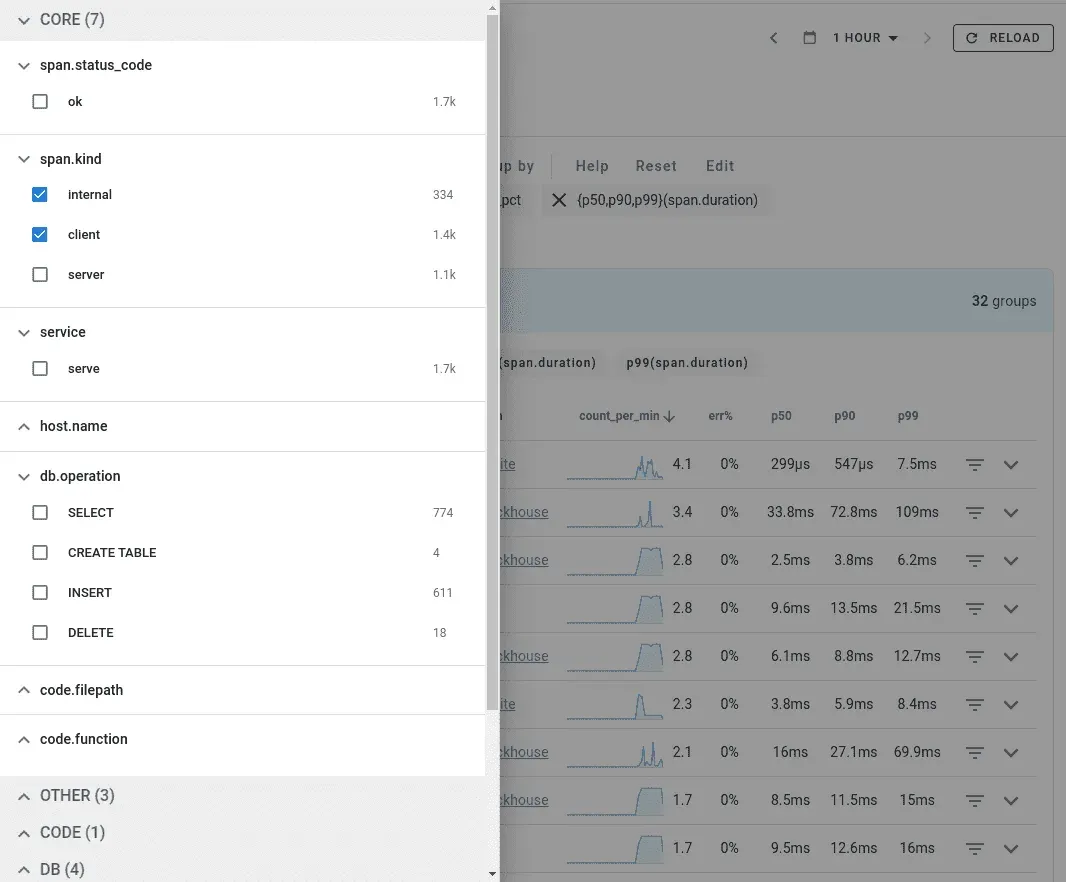
- SQL-like span queries Spans and logs are grouped and aggregated with an SQL-like language (span querying). Version 2.1 adds compound trace expressions,
quantile(), arithmetic inhavingand cross-join queries across spans of the same trace.count()now always counts spans, withcountDistinct()for distinct values. - PromQL-like metric queries Metrics are queried with a PromQL-like language described in the metrics querying guide. The 2.1 changelog lists PromQL-compatible rollup functions,
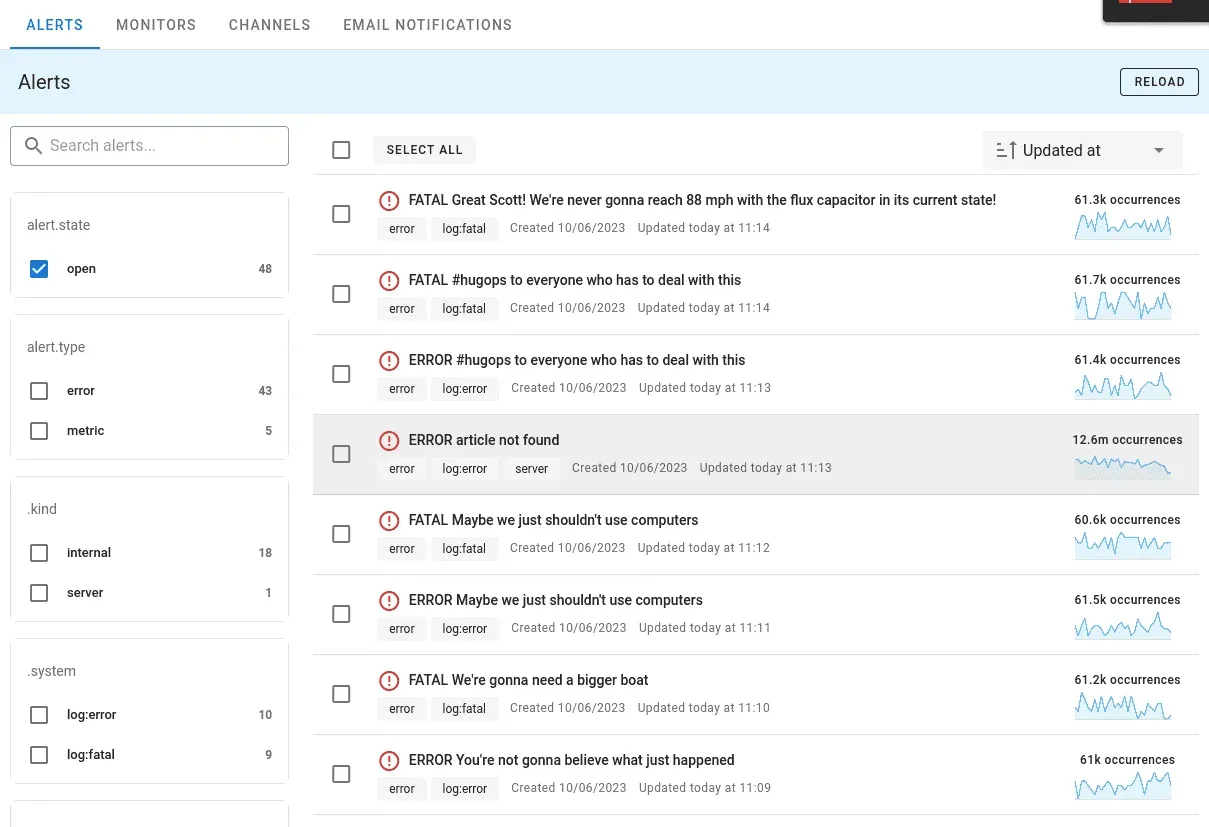
stddev,stdvarandhaving. Prometheus remote write 2.0 and native histograms are accepted. - Alerting and notification channels Monitors watch spans, logs and metrics and send notifications by email, Slack, webhook, Alertmanager, Opsgenie, incident.io and Pushover, as described in the alerting documentation. Alert policies can set attributes, priority or archive matching alerts, and monitors or channels can be paused for a set time.
- Incidents and SLOs Related alerts are grouped into incidents with priority, owners, status, timeline and notes. Service level objectives track error budgets over rolling windows with burn-rate and budget-spent rules, and can be imported and exported as YAML. Incident grouping can be manual and does not require an AI model provider.
- Anomaly, outlier and forecast monitors Metric monitors support seasonality, sensitivity presets, K-of-N confirmation and level-shift detection. They can be previewed and backtested on interactive charts, and each alert includes an explanation of how the decision was made.
- Wide ingestion options Besides OTLP over gRPC and HTTP, Uptrace ingests data from Prometheus, Vector, FluentBit, CloudWatch and other sources. Each project token also has a Sentry DSN, so Sentry SDKs can send errors, breadcrumbs and stack traces, and JavaScript source maps can be uploaded for symbolication.
- Grafana compatibility Grafana can use Uptrace as a Tempo or Prometheus data source, according to the Grafana integration page. This lets existing Grafana dashboards query traces and metrics stored in Uptrace.
- Single sign-on and access control Users and projects can be managed in the YAML configuration. Sign-in with OpenID Connect is documented for Keycloak, Google Cloud and Cloudflare, and SAML requests are signed with SHA-256. On self-hosted editions, RBAC starts with the Team tier and SSO with the Business tier.
- MCP server and issue trackers An MCP server lets AI assistants read project data and dashboards; the Project tab shows how to configure it. GitHub or Forgejo issues can be created from any span or error group, with an editable description and a link back to the source.
- Storage efficiency and retention The project states processing of more than 10,000 spans per second on a single core and compression of a 1 KB span to about 40 bytes. Each project can set retention per signal within limits set by the deployment, and the Community edition includes 14 days of retention.
- Self-hosted deployment methods Docker Compose starts Uptrace with ClickHouse, PostgreSQL, Redis, an OpenTelemetry Collector and Mailpit from the
example/dockerfolder, with the UI on port 14318. The Helm chart creates about 23 GiB of persistent volumes with default values, and an Ansible playbook targets bare-metal servers. The installation guide sizes 30 TB of spans and logs with 2 million time series at 24 vCPU, 48 GB RAM, 1 TB SSD and 6 TB HDD. - Packages and binaries Each GitHub release ships DEB and RPM packages for amd64 and arm64, plus standalone binaries for Linux amd64 and arm64, macOS amd64 and arm64 and Windows amd64, with a checksums file. The DEB and RPM packages start or restart the service only when no migration is pending.
- Self-hosted editions The editions page lists Community at $0 with unlimited usage, basic alerting and community support; Starter at $39 per month up to 50 GB per day; Team at $199 per month up to 200 GB per day; Business at $499 per month up to 500 GB per day; and a custom Enterprise tier. Daily limits are measured as a 30-day average, and reaching a limit disables premium features without dropping data.
- Uptrace Cloud pricing The cloud pricing page lists 50 GB free per month, per-GB rates that decrease with volume, metrics billed per million datapoints and no charge per user, service or host. Cloud data is kept for 28 days by default, with cold storage for up to 100 weeks. Billing is handled by Paddle, and a monthly budget cap can be set.
- Upgrade tooling
uptrace migrate upmigrates PostgreSQL and ClickHouse together in phases so ingestion continues during an upgrade,uptrace preflightchecks database versions anduptrace config fix --writerewrites renamed options. The upgrade guide asks for PostgreSQL and ClickHouse backups first.
Where Uptrace fits
Tracing microservices with OpenTelemetry
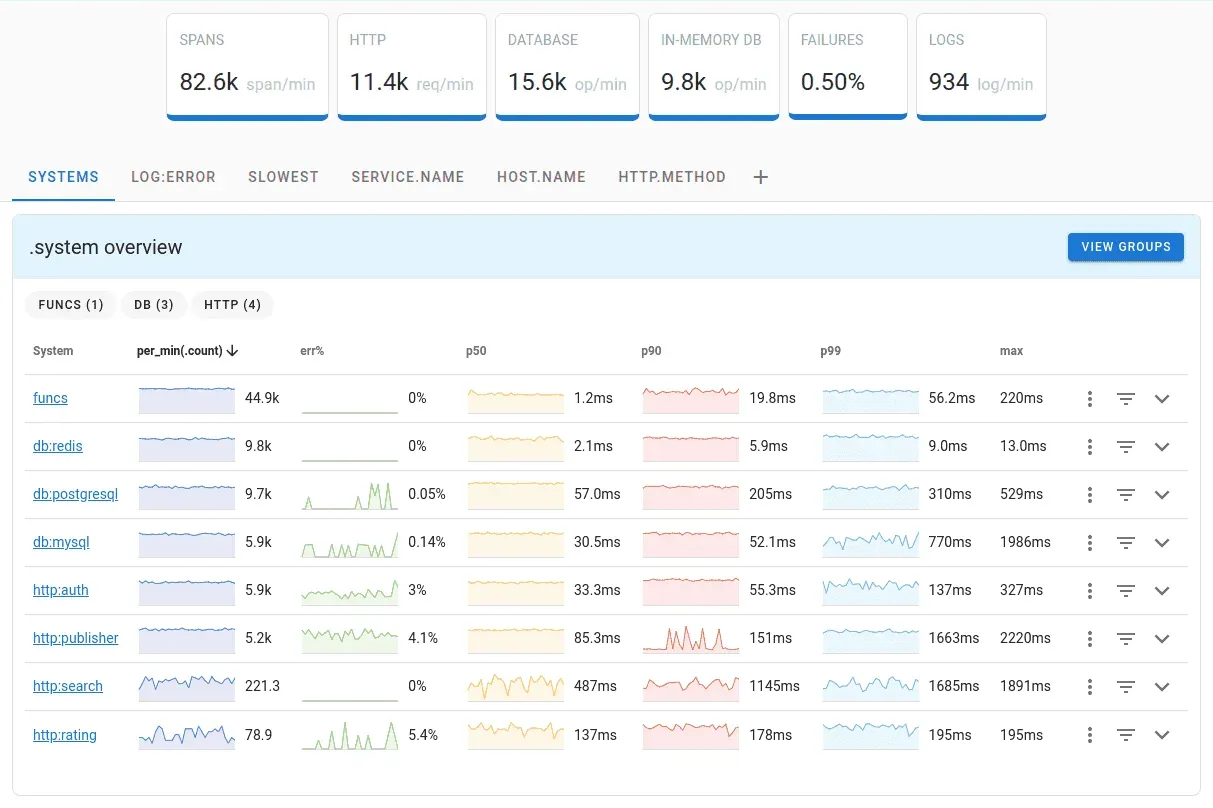
Services are instrumented with an OpenTelemetry SDK or zero-code instrumentation and send spans to Uptrace with a project DSN, which bundles the endpoint and access token. Spans are grouped by system and operation with p50, p90 and p99 latency, error rate and rate per minute, and the service graph shows dependencies with per-node metrics. The getting started guide lists language-specific distributions.
Infrastructure and database metrics
Metrics arrive from the OpenTelemetry Collector or Prometheus remote write, and Uptrace creates matching dashboards automatically, for example Redis nodes with CPU, memory, connections and request rate. Queries in the PromQL-like language group, filter and aggregate time series, and anomaly or forecast monitors can watch them.
Log search and error tracking
Logs from Vector, FluentBit, CloudWatch or OpenTelemetry are stored next to spans, so logs can be linked to traces. Version 2.1 adds full-text search over spans and logs, log grouping rules that can be tested on sample lines, and Sentry SDK ingestion with breadcrumbs, structured stack traces and source map symbolication for JavaScript.
On-call alerting and incident handling
Monitors on spans, logs and metrics feed alerts, which alert policies can reprioritise or archive and which are grouped into incidents with owners, status and timeline. Notifications go to email, Slack, webhooks, Alertmanager, Opsgenie, incident.io or Pushover, and monitor descriptions such as runbook links appear in notifications. SLO burn-rate rules alert on error budget consumption.
Running observability inside one's own network
Self-hosted Uptrace keeps all telemetry in the operator's own ClickHouse, PostgreSQL and Redis instances. The editions page describes this as suited to compliance and air-gapped setups. Operators choose Docker Compose, Helm, Ansible or a manual install, and the scaling guide covers pipeline tuning, ClickHouse inserts and Kafka for high volume.
Using Grafana and AI assistants with Uptrace data
Teams that already use Grafana can add Uptrace as a Tempo or Prometheus data source and keep their existing dashboards. The built-in MCP server exposes project data and dashboards to AI assistants, and the incident view can request an AI analysis with recommendations for review.
Install
git clone https://github.com/uptrace/uptrace.git && cd uptrace/example/docker && docker compose up -dReviews of Uptrace
Be the first to share your experience with Uptrace.
Write a review
Loading review form…
Found Uptrace useful? Upvote it todayYour vote helps other IT teams find it in the daily ranking.


